<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://carriagereturn.nl/feed.xml" rel="self" type="application/atom+xml" /><link href="https://carriagereturn.nl/" rel="alternate" type="text/html" /><updated>2026-05-24T14:51:36+00:00</updated><id>https://carriagereturn.nl/feed.xml</id><title type="html">CarriageReturn.Nl</title><subtitle>About builders, building stuff, getting things done and lessons learned on public cloud.</subtitle><entry><title type="html">Can You Keep a Secret?</title><link href="https://carriagereturn.nl/aws/ec2/attestation/kms/secret/2026/05/24/keeping-secrets.html" rel="alternate" type="text/html" title="Can You Keep a Secret?" /><published>2026-05-24T06:00:00+00:00</published><updated>2026-05-24T06:00:00+00:00</updated><id>https://carriagereturn.nl/aws/ec2/attestation/kms/secret/2026/05/24/keeping-secrets</id><content type="html" xml:base="https://carriagereturn.nl/aws/ec2/attestation/kms/secret/2026/05/24/keeping-secrets.html"><![CDATA[<p>Here’s the challenge: You’re a SaaS vendor closing a deal with a major customer — but with one condition.
Your product must run inside their AWS account. You want the deal. But that means your competitive advantage,
the secret sauce that makes your product unique, is now deployed into an account you don’t control. It could
be proprietary application logic or carefully crafted LLM prompts that took months to get right.</p>

<p>IAM policies won’t save you. Encryption at rest won’t either — not when the account administrator has access
to the keys and can reach anything in their account. But there is a way to keep your secret …</p>

<h2 id="ec2-instance-attestation">EC2 Instance Attestation</h2>

<p>AWS documentation describes <a href="https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/nitrotpm-attestation.html">attestation</a> as</p>

<blockquote>
  <p>Attestation is a process that allows you to cryptographically prove to any party that only trusted software, drivers, and boot processes are running on an Amazon EC2 instance. Amazon EC2 instance attestation is powered by the Nitro Trusted Platform Module (NitroTPM) and Attestable AMIs.</p>
</blockquote>

<p>Above doesn’t do a very good job of describing what this feature is good for. There are 2 major use-cases
for attestation. First it can be used as evidence for an auditor to show instance has not been tampered
and has a known configuration. The second case, which I focus on in this post, is that this evidence can be used
in KMS key policy condition to allow or deny decryption of secrets. When this is combined with OS level
security measures such as <a href="https://docs.kernel.org/filesystems/erofs.html">enhanced read-only file system</a> (erofs) and <a href="https://www.kernel.org/doc/html/latest/admin-guide/device-mapper/verity.html">device-mapper verity</a>
(dm-verity) it is possible to deliver secrets to an environment that is safe even from the account owner.</p>

<p>Instance attestation is based on Nitro Trusted Platform Module (TPM) which is hardware that acts as
a digital vault generating and storing sensitive information. You likely have one in your laptop.
It stores biometric data and powers drive encryption.</p>

<h3 id="test-scenario">Test Scenario</h3>

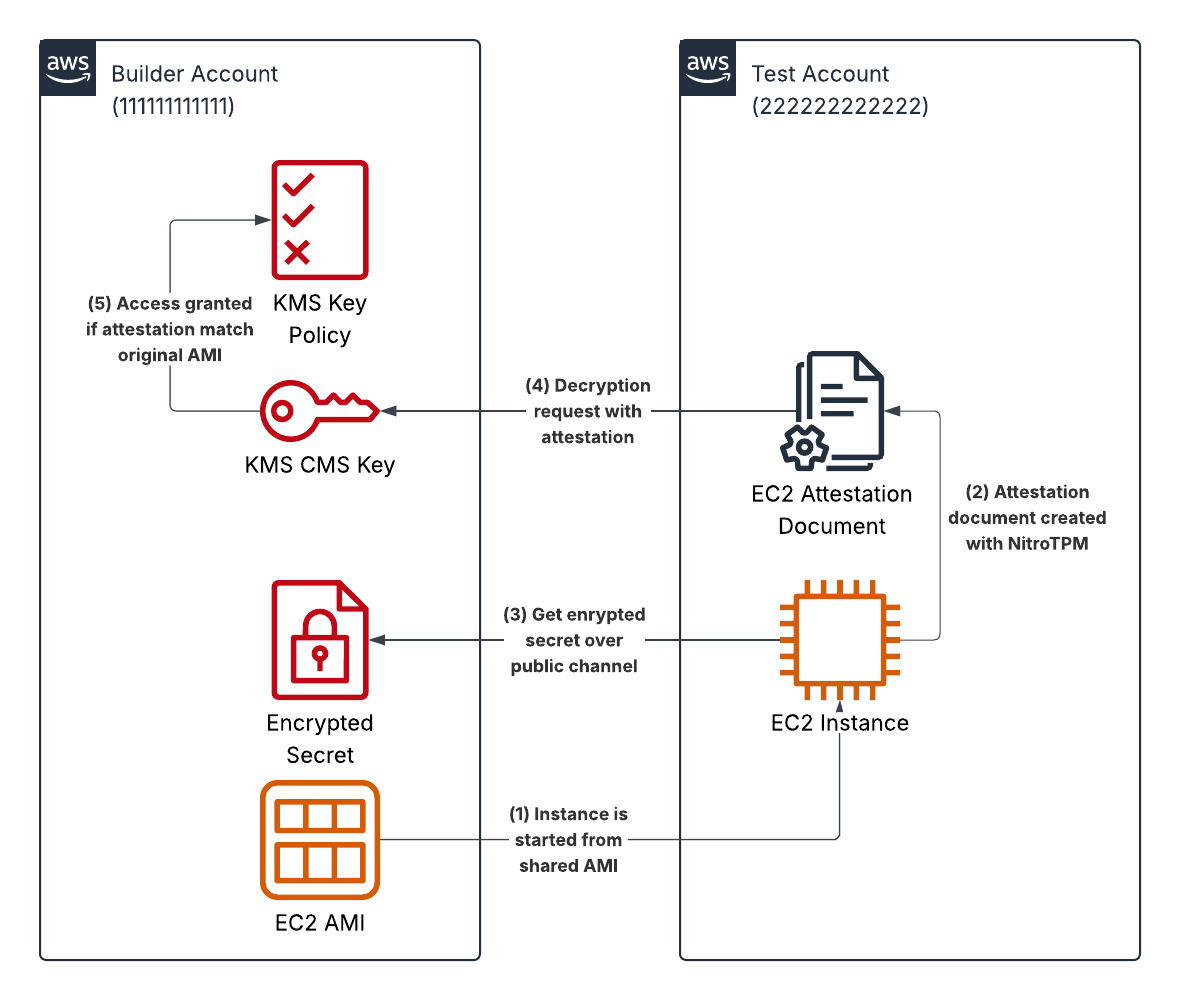
<p>The diagram below shows the test scenario across two AWS accounts:</p>

<ul>
  <li>Builder Account owns the attestable AMI, the KMS CMS key, and the encrypted secret. This is your account as the SaaS vendor.</li>
  <li>Test Account represents the customer’s account where your product will actually run.</li>
</ul>

<ol>
  <li>Instance launch — The test account starts an EC2 instance from the AMI shared by the builder account. Because the AMI is attestable, NitroTPM measures the boot chain into PCR registers.</li>
  <li>Attestation document — On the running instance, NitroTPM produces a signed attestation document containing the current PCR values and a public key supplied by the caller.</li>
  <li>Fetch encrypted secret — The instance retrieves the encrypted secret over a public channel. The ciphertext is not sensitive on its own — it can only be opened with the KMS key in the builder account.</li>
  <li>Decryption request — The instance calls kms:Decrypt against the builder account’s KMS key, attaching the attestation document as the recipient.</li>
  <li>Policy evaluation — The KMS key policy compares the PCR values in the attestation document to the expected values from the original AMI build. If they match, KMS returns the plaintext wrapped with the public key from step 2, so only the attested instance can unwrap it.</li>
</ol>

<p>The secret is delivered into the customer’s account but never visible to the account administrator - only to a process running on an instance booted from an AMI the builder built and measured.</p>

<p><a href="/img/attestation/setup.png"><img src="/img/attestation/setup.png" width="100%" /></a></p>

<h3 id="ec2-instance-types-with-nitrotpm">EC2 Instance Types with NitroTPM</h3>

<p>Even though NitroTPM is widely supported by EC2 instance families, not all families have it,
and not all regions have all families. You can find this info from AWS documentation and
AWS API using <code class="language-plaintext highlighter-rouge">aws ec2 describe-instance-types</code> but it is a bit clumsy. So I wrote <a href="https://github.com/kallu/ec2attestion/blob/main/ec2-tpm-support.sh">a utility
script</a> to list NitroTPM supported EC2 families in given region
when no arguments are given, or list available instance types when one or multiple families
are specified in cmd line.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>% <span class="nb">export </span><span class="nv">AWS_REGION</span><span class="o">=</span>eu-north-1
% ./ec2-tpm-support.sh        
c: c5 c5a c5d c5n c6g c6gd c6gn c6i c6in c7a c7g c7gd c7i c7i-flex c8g c8gn
g: g4dn g5 g6 g6e g6f
gr: gr6 gr6f
hpc: hpc6a hpc6id hpc8a
i: i3en i4i i7i i7ie i8g i8ge
inf: inf1 inf2
m: m5 m5d m6g m6gd m6i m6idn m6in m7a m7g m7gd m7i m7i-flex m8g
p: p5 p5e p5en
r: r5 r5b r5d r5dn r5n r6g r6gd r6i r6idn r6in r7a r7g r7gd r7i r8g
t: t3 t4g
u: u7i-12tb u7i-6tb u7i-8tb u7in-24tb
x: x2idn x2iedn x8aedz x8g x8i
</code></pre></div></div>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>% ./ec2-tpm-support.sh c7g m5
c7g: c7g.12xlarge c7g.16xlarge c7g.2xlarge c7g.4xlarge c7g.8xlarge c7g.large c7g.medium c7g.xlarge
m5: m5.12xlarge m5.16xlarge m5.24xlarge m5.2xlarge m5.4xlarge m5.8xlarge m5.large m5.xlarge
</code></pre></div></div>

<h2 id="attestable-ami">Attestable AMI</h2>

<p>To use EC2 attestation not just any AMI works. I need to build an attestable AMI. This is an AMI
for which I have PCR hash values. PCRs (Platform Configuration Registers) are TPM slots that accumulate
hashes of each step in the boot chain. They can’t be written directly — only extended — so the final
values are a tamper-evident fingerprint of exactly what booted. KMS can use these values to decide
whether to allow decrypting the secret.</p>

<p>To simplify the build process I wrote a <a href="https://github.com/kallu/ec2attestion/blob/main/cloudformation/build-instance.yaml">template</a> that creates
an EC2 instance with either an x86 or arm64 CPU using the latest Amazon Linux 2023 AMI. Instance can be
accessed with SSM Session Manager.</p>

<p>AMI build starts by installing required packages …</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>dnf <span class="nb">install</span> <span class="nt">-y</span> <span class="se">\</span>
  kiwi-cli python3-kiwi kiwi-systemdeps-core <span class="se">\</span>
  qemu-img veritysetup erofs-utils git cargo <span class="se">\</span>
  kiwi-image-descriptions-examples
</code></pre></div></div>

<p>Then I build coldsnap utility, which simplifies AMI build process by skipping snapshotting
a running instance step. Coldsnap pulls in aws-sdk-ec2, which takes a while to compile and needs 16 GB
of RAM. This is the reason build-template is using r7*.large instance.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone https://github.com/awslabs/coldsnap.git <span class="o">&amp;&amp;</span> <span class="o">(</span><span class="nb">cd </span>coldsnap <span class="o">&amp;&amp;</span> cargo <span class="nb">install</span> <span class="nt">--locked</span> coldsnap<span class="o">)</span>
</code></pre></div></div>

<p>For my demo case, I’m using the sample <a href="https://github.com/kallu/ec2attestion/blob/main/appliance.kiwi">appliance description</a> that comes with <a href="https://osinside.github.io/kiwi/index.html">Kiwi</a>,
with minor modifications to make it work better in the demo; I added <code class="language-plaintext highlighter-rouge">openssl</code> and <code class="language-plaintext highlighter-rouge">tpm2-tools</code> packages
and installed <code class="language-plaintext highlighter-rouge">amazon-ssm-agent</code> so I can login to instance and show secrets can be decrypted.
In real life you would not install ssm-agent as it would let account owner login to instance.</p>

<p>I’m skipping most of the image configuration details in this post but you can find more details in
<a href="https://osinside.github.io/kiwi/index.html">Kiwi documentation</a> and <a href="https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/attestable-ami.html">Attestable AMIs</a> &amp; <a href="https://aws.amazon.com/blogs/compute/deep-dive-into-nitrotpm-and-uefi-secure-boot-support-in-amazon-ec2/">NitroTPM deep dive</a>.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>        &lt;!-- NOTE: additional packages for demo --&gt;
        &lt;package name="openssl"/&gt;
        &lt;package name="tpm2-tools"/&gt;
        ...
        &lt;!-- Remove operator access by not installing these packages --&gt;
        &lt;!-- NOTE: SSM agent is installed for demo --&gt;
        &lt;ignore name="openssh-server"/&gt;
        &lt;package name="amazon-ssm-agent"/&gt;
        &lt;ignore name="cloud-init"/&gt;
        &lt;ignore name="cloud-init-cfg-ec2"/&gt;
        &lt;ignore name="update-motd" /&gt;
        &lt;ignore name="ec2-instance-connect"/&gt;
        ...       
</code></pre></div></div>

<p>After modifying <code class="language-plaintext highlighter-rouge">/usr/share/kiwi-image-descriptions-examples/al2023/attestable-image-example/appliance.kiwi</code>
I was ready to build the AMI and get PCR measurements. If you’re wondering, the PCR measurements below are not from
a real AMI — they’re random hex strings ;-)</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kiwi-ng system build <span class="se">\</span>
  <span class="nt">--description</span> /usr/share/kiwi-image-descriptions-examples/al2023/attestable-image-example <span class="se">\</span>
  <span class="nt">--target-dir</span> ./image

<span class="nb">cat</span> ./image/pcr_measurements.json
<span class="o">{</span>
  <span class="s2">"Measurements"</span>: <span class="o">{</span>
    <span class="s2">"HashAlgorithm"</span>: <span class="s2">"SHA384"</span>,
    <span class="s2">"PCR4"</span>: <span class="s2">"a3f7c2e891b4d56f0a2c8e1d7b3f4956c0a8e2d1f7b394c5e6a0d2f8b1c4e7a3d5f6c8b0e2a4d7f1c3b5e8a0d2f4c6b9"</span>,
    <span class="s2">"PCR7"</span>: <span class="s2">"d2f8a1c4e7b390d5f2c6a8e1b4d7f0c3a5e9b2d6f8c1a4e7b0d3f6c9a2e5b8d1f4c7a0e3b6d9f2c5a8e1b4d7f0c3a5e9"</span>,
    <span class="s2">"PCR12"</span>: <span class="s2">"000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000"</span>
  <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>

<p>Next I uploaded the snapshot and register AMI. I learned it the hard way to avoid throttlin and limit upload process using <code class="language-plaintext highlighter-rouge">--workers 16 --omit-zero-blocks</code>. If you still get throttling errors from AWS, you can tune it down further.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>SNAPSHOT=$(~/.cargo/bin/coldsnap upload --workers 16 --omit-zero-blocks ./image/al2023*.raw)
ARCH=$(m=$(uname -m); [ "$m" = "aarch64" ] &amp;&amp; m="arm64"; echo "$m")
aws ec2 wait snapshot-completed --snapshot-ids ${SNAPSHOT} || exit 1
aws ec2 register-image \
  --name "attestable-app-$(date +%Y%m%d-%H%M)" \
  --architecture ${ARCH} \
  --boot-mode uefi \
  --tpm-support v2.0 \
  --ena-support \
  --virtualization-type hvm \
  --root-device-name /dev/xvda \
  --block-device-mappings DeviceName=/dev/xvda,Ebs={SnapshotId=${SNAPSHOT}}
</code></pre></div></div>

<p>Then I shared the AMI with the AWS test account.</p>

<p>NOTE: Remember to terminate the build instance once the AMI is ready.</p>

<h2 id="kms-key-policy">KMS Key Policy</h2>

<p>Next I need a KMS key to encrypt and decrypt my secret. The focus is on the key policy that must allow all actions
from my builder account where the key is created, and allow decryption from remote accounts only if a correct
attestation document is provided. I wrote a <a href="https://github.com/kallu/ec2attestion/blob/main/cloudformation/kms.yaml">template</a> that takes PCR4 value (see above) as
input and creates a key (and alias) with proper policy. Take note of <code class="language-plaintext highlighter-rouge">AttestationKeyAlias</code> in stack output.
This is required later when testing.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>    - Sid: AllowAttestedDecryptAnyAccount
      Effect: Allow
      Principal: '*'
      Action:
        - kms:Decrypt
        - kms:GenerateDataKey
        - kms:GenerateRandom
      Resource: '*'
      Condition:
        StringEqualsIgnoreCase:
          kms:RecipientAttestation:NitroTPMPCR4:  !Ref PCR4Value
          kms:RecipientAttestation:NitroTPMPCR12: '000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000000'
</code></pre></div></div>

<h2 id="testing">Testing</h2>

<p>Let’s start by creating an EC2 instance on test account (one that doesn’t have KMS key). This instance must support NitroTPM
and <a href="https://github.com/aws/NitroTPM-Tools/issues/7">can not be T-series</a> because of a limitation in TPM. I wrote a <a href="https://github.com/kallu/ec2attestion/blob/main/cloudformation/test-instance.yaml">template</a>
to help set up an instance with SSM Session Manager access (remember ssm was deployed to AMI for testing). Use AMI ID
from build account that was shared earlier.</p>

<h3 id="encrypting">Encrypting</h3>

<p>On build account I use the KMS to encrypt a secret. Take note of encrypted <code class="language-plaintext highlighter-rouge">$BLOB</code>. Use key alias id from KMS stack output.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>SECRET="Hello World"
B64=$(echo "$SECRET" | base64)
BLOB=$(aws kms encrypt --key-id arn:aws:kms:eu-north-1:111111111111:alias/sample-kms-key --plaintext ${B64} --query CiphertextBlob --output text)
</code></pre></div></div>

<h3 id="decrypting">Decrypting</h3>

<p>Let’s start by verifying I can decrypt on build account where I encrypted my secret.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>aws kms decrypt --key-id arn:aws:kms:eu-north-1:111111111111:alias/sample-kms-key --ciphertext-blob "${BLOB}" --query Plaintext --output text | base64 -d
Hello World
</code></pre></div></div>

<p>Above works only when called from build account. If I run the same on test account, key policy will prevent decryption with an error.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>aws: [ERROR]: An error occurred (AccessDeniedException) when calling the Decrypt operation: User: arn:aws:sts::22222222222:assumed-role/OrganizationAccountAccessRole/user@example.com is not authorized to perform: kms:Decrypt on the resource associated with this ciphertext because the resource does not exist in this Region, no resource-based policies allow access, or a resource-based policy explicitly denies access
</code></pre></div></div>

<p>When I login to EC2 instance created from attested AMI on test account, I can decrypt the secret with attestation document.
First let’s set some variables to hold encrypted data and define the KMS key alias for decryption. As the secret is now
encrypted it can be shared over public channels to test instance.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>CIPHERTEXT_B64="YOUR_ENCRYPTED_BLOB"
echo "$CIPHERTEXT_B64" | base64 -d &gt; /tmp/ct.bin
KMS_KEY_ID="arn:aws:kms:eu-north-1:111111111111:alias/sample-kms-key"
</code></pre></div></div>

<p>Then I need an ephemeral key-pair for the decryption process. When called with <code class="language-plaintext highlighter-rouge">--recipient</code>, KMS won’t return plaintext
over the wire to an attested instance; instead it wraps the plaintext with the public key in the attestation document.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>openssl genrsa -out /tmp/priv.pem 2048
openssl rsa -in /tmp/priv.pem -pubout -outform DER -out /tmp/pub.der
</code></pre></div></div>

<p>I created those into /tmp to keep data in memory even though this isn’t strictly necessary as my AMI boots to read-only
filesystem with overlay so all writes are stored to instance memory and not written to EBS volume. The public key is
sent to KMS inside the attestation document, where it’s used to encrypt the reply.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ATT=$(/usr/bin/nitro-tpm-attest --public-key /tmp/pub.der | base64 -w0)
</code></pre></div></div>

<p>NOTE: Attestation document is only valid for 5 minutes after it has been created. If you get error for expired document
when decrypting with KMS, just rerun above to refresh.</p>

<p>Now I can decrypt the secret.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>aws kms decrypt --key-id "$KMS_KEY_ID" \
  --ciphertext-blob fileb:///tmp/ct.bin \
  --recipient "KeyEncryptionAlgorithm=RSAES_OAEP_SHA_256,AttestationDocument=${ATT}" \
  --query CiphertextForRecipient \
  --output text | base64 -d &gt; /tmp/wrapped.bin
</code></pre></div></div>

<p>KMS doesn’t return the plaintext directly — the secret arrives encrypted with the ephemeral key-pair
I must decrypt with matching private key.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>openssl cms -decrypt -inform DER -in /tmp/wrapped.bin -inkey /tmp/priv.pem
Hello World
</code></pre></div></div>

<h2 id="summary">Summary</h2>

<p>The demonstration above showed how to deliver a secret to an EC2 instance in a remote AWS account without
exposing it to the account owner. To keep the process secure do remember</p>

<ul>
  <li>AMI containing the application must have all external access disabled.
This includes inbound network access like sshd, SSM agent, and instance connect.
Also cloud-init must be disabled to prevent user-data script from adding any
access during the instance boot.</li>
  <li>PCR value used in KMS key policy must be kept secret. If it gets compromised, 
an attacker can create a valid attestation document and gain access to KMS key.</li>
  <li>You can (and should) limit access to KMS key only to your customer accounts.
Sharing the key with everyone adds risk if PCR gets compromised.</li>
  <li>The AMI itself should not be considered secret — it’s trivial to create 
an EBS volume from it and attach it to an attacker-controlled instance.
You can embed encrypted secrets in the AMI, but it’s not recommended: 
you’d need to update the PCR values in KMS policy every time the AMI changes.</li>
  <li>When processing the data you should never write plaintext secrets to disk but 
keep it in memory so an attacker can’t recover it from a EBS snapshot. 
Having read-only file system helps to keep data off the disk ;-)</li>
  <li>If you must store a secret data to a disk, use OS block level encryption 
such as <a href="https://en.wikipedia.org/wiki/Linux_Unified_Key_Setup">LUKS</a>. AWS native EBS encryption is not secure because 
it doesn’t support attestation.</li>
</ul>

<p>You can find templates, scripts and other supporting documents from <a href="https://github.com/kallu/ec2attestion/tree/main">ec2attestation github repo</a>.
There is also further details on <a href="https://github.com/kallu/ec2attestion/blob/main/tamper.md">tampering the AMI</a> and using <a href="https://github.com/kallu/ec2attestion/blob/main/luks.md">encrypted file system</a>.
These were too much to be included in a single blog post. Also beware these were written with help
from Claude and all details haven’t been verified.</p>]]></content><author><name>kallu</name></author><category term="aws" /><category term="ec2" /><category term="attestation" /><category term="kms" /><category term="secret" /><summary type="html"><![CDATA[You're a SaaS vendor closing a deal with a major customer — but with one condition. Your product must run inside their AWS account. You want the deal. But that means your competitive advantage, the secret sauce that makes your product unique, is now deployed into an account you don't control. IAM policies won't save you. Encryption at rest won't either — not when the account administrator has access to the keys and can reach anything in their account. But there is a way to keep your secret ...]]></summary></entry><entry><title type="html">Building a self-synchronizing Bedrock knowledge base with S3 Vector</title><link href="https://carriagereturn.nl/aws/s3/vector/bedrock/knowledgebase/2026/01/18/s3-knowledge-base.html" rel="alternate" type="text/html" title="Building a self-synchronizing Bedrock knowledge base with S3 Vector" /><published>2026-01-18T16:00:00+00:00</published><updated>2026-01-18T16:00:00+00:00</updated><id>https://carriagereturn.nl/aws/s3/vector/bedrock/knowledgebase/2026/01/18/s3-knowledge-base</id><content type="html" xml:base="https://carriagereturn.nl/aws/s3/vector/bedrock/knowledgebase/2026/01/18/s3-knowledge-base.html"><![CDATA[<p>Amazon S3 Vectors became <a href="https://aws.amazon.com/blogs/aws/amazon-s3-vectors-now-generally-available-with-increased-scale-and-performance/">generally available in December 2025</a>, bringing native vector storage to Amazon Simple Storage Service (S3) with the capacity to store up to 2 billion vectors per index (a 40x increase from preview) and sub-100ms query latencies. And while doing that, it can also reduce RAG infrastructure costs by up to 90% compared to traditional vector databases, making it suitable not just for very large but also for very small usage cases.</p>

<p>This post demystifies the process of setting up S3 Vector based Knowledge Bases for Amazon Bedrock by walking through complete implementation in AWS CloudFormation. Examining the infrastructure as code will reveal components, dependencies, and permissions required—bringing full transparency to the “magic” that happens when the same is <a href="https://aws.amazon.com/blogs/machine-learning/building-cost-effective-rag-applications-with-amazon-bedrock-knowledge-bases-and-amazon-s3-vectors/">build from Amazon Web Services (AWS) console</a>.</p>

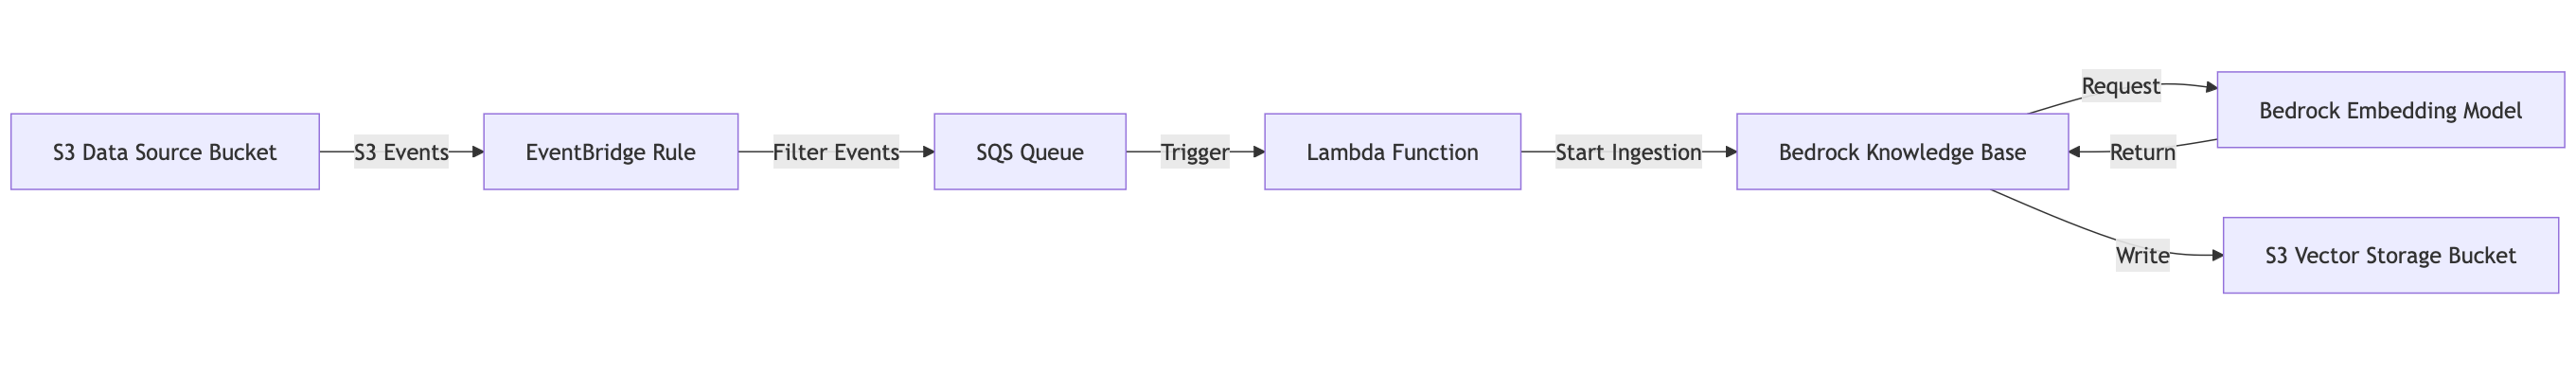
<p>But I will also add some magic ;-) sync mechanism that keeps the knowledge base synchronized with S3 changes automatically. Here’s the complete flow that CloudFormation will build. Click the image to enlarge.</p>

<p><a href="/img/bedrock-kb-s3/diagram1.png"><img src="/img/bedrock-kb-s3/diagram1.png" width="100%" /></a></p>

<p>The complete CloudFormation template is available in the <a href="https://github.com/kallu/aws-bedrock-kb-s3-vector">aws-bedrock-kb-s3-vector</a> repository.</p>

<h3 id="the--policies">The  Policies</h3>
<p>Let’s start from the AWS Identity and Access Management (IAM) roles — this is where the console hides most details.</p>

<p><strong>Bedrock Knowledge Base Role</strong> (<code class="language-plaintext highlighter-rouge">KnowledgeBaseRole</code>):</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">AssumeRolePolicyDocument</span><span class="pi">:</span>
  <span class="na">Statement</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="na">Effect</span><span class="pi">:</span> <span class="s">Allow</span>
      <span class="na">Principal</span><span class="pi">:</span>
        <span class="na">Service</span><span class="pi">:</span> <span class="s">bedrock.amazonaws.com</span>
      <span class="na">Action</span><span class="pi">:</span> <span class="s">sts:AssumeRole</span>
      <span class="na">Condition</span><span class="pi">:</span>
        <span class="na">StringEquals</span><span class="pi">:</span>
          <span class="na">aws:SourceAccount</span><span class="pi">:</span> <span class="kt">!Ref</span> <span class="s">AWS::AccountId</span>
        <span class="na">ArnLike</span><span class="pi">:</span>
          <span class="na">aws:SourceArn</span><span class="pi">:</span> <span class="kt">!Sub</span> <span class="s1">'</span><span class="s">arn:aws:bedrock:${AWS::Region}:${AWS::AccountId}:knowledge-base/*'</span>
</code></pre></div></div>

<p>This trust policy allows the Bedrock service to assume the role, but ONLY:</p>
<ul>
  <li>From your AWS account (prevents cross-account access)</li>
  <li>When acting on behalf of a knowledge base resource (not other Bedrock features)</li>
</ul>

<p><strong>Knowledge Base Permissions</strong>:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Policies</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="na">PolicyName</span><span class="pi">:</span> <span class="s">S3Access</span>
    <span class="na">PolicyDocument</span><span class="pi">:</span>
      <span class="na">Statement</span><span class="pi">:</span>
        <span class="c1"># Read from data source bucket</span>
        <span class="pi">-</span> <span class="na">Effect</span><span class="pi">:</span> <span class="s">Allow</span>
          <span class="na">Action</span><span class="pi">:</span>
            <span class="pi">-</span> <span class="s">s3:GetObject</span>
            <span class="pi">-</span> <span class="s">s3:ListBucket</span>
          <span class="na">Resource</span><span class="pi">:</span>
            <span class="pi">-</span> <span class="kt">!Sub</span> <span class="s1">'</span><span class="s">${DataSourceBucket.Arn}'</span>
            <span class="pi">-</span> <span class="kt">!Sub</span> <span class="s1">'</span><span class="s">${DataSourceBucket.Arn}/*'</span>

        <span class="c1"># Write to vector storage bucket</span>
        <span class="pi">-</span> <span class="na">Effect</span><span class="pi">:</span> <span class="s">Allow</span>
          <span class="na">Action</span><span class="pi">:</span>
            <span class="pi">-</span> <span class="s">s3:PutObject</span>
            <span class="pi">-</span> <span class="s">s3:GetObject</span>
            <span class="pi">-</span> <span class="s">s3:ListBucket</span>
          <span class="na">Resource</span><span class="pi">:</span>
            <span class="pi">-</span> <span class="kt">!Sub</span> <span class="s1">'</span><span class="s">${VectorStorageBucket.Arn}'</span>
            <span class="pi">-</span> <span class="kt">!Sub</span> <span class="s1">'</span><span class="s">${VectorStorageBucket.Arn}/*'</span>

        <span class="c1"># Invoke embedding model</span>
        <span class="pi">-</span> <span class="na">Effect</span><span class="pi">:</span> <span class="s">Allow</span>
          <span class="na">Action</span><span class="pi">:</span>
            <span class="pi">-</span> <span class="s">bedrock:InvokeModel</span>
          <span class="na">Resource</span><span class="pi">:</span> <span class="kt">!Sub</span> <span class="s1">'</span><span class="s">arn:aws:bedrock:${AWS::Region}::foundation-model/${EmbeddingModelId}'</span>
</code></pre></div></div>

<p>NOTE:</p>
<ul>
  <li>Data source: Read-only access</li>
  <li>Vector storage: Read/write access</li>
  <li>Embedding model: Invoke permission scoped to specific model</li>
</ul>

<p><strong>AWS Lambda Execution Role</strong> (<code class="language-plaintext highlighter-rouge">AutoSyncLambdaRole</code>):</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Policies</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="na">PolicyName</span><span class="pi">:</span> <span class="s">BedrockIngestionAccess</span>
    <span class="na">PolicyDocument</span><span class="pi">:</span>
      <span class="na">Statement</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="na">Effect</span><span class="pi">:</span> <span class="s">Allow</span>
          <span class="na">Action</span><span class="pi">:</span>
            <span class="pi">-</span> <span class="s">bedrock-agent:StartIngestionJob</span>
            <span class="pi">-</span> <span class="s">bedrock-agent:ListIngestionJobs</span>
          <span class="na">Resource</span><span class="pi">:</span>
            <span class="pi">-</span> <span class="kt">!Sub</span> <span class="s1">'</span><span class="s">arn:aws:bedrock:${AWS::Region}:${AWS::AccountId}:knowledge-base/${KnowledgeBase}'</span>
</code></pre></div></div>

<p>NOTE: Lambda can only interact with this specific knowledge base.</p>

<h2 id="the-chunking-strategies">The Chunking Strategies</h2>

<p>The console shows you <a href="https://builder.aws.com/content/2j9KouvnFz4zVdtsXcbMpN3G6Cw/genai-under-the-hood-part-8-a-visual-guide-to-advanced-chunking-strategies">chunking options</a> in a simple dropdown. But each strategy requires different configuration resource type in CloudFormation.
This makes switching the strategy bit more complex than it first seems.</p>

<h3 id="fixed-size-chunking">Fixed-Size Chunking</h3>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">ChunkingConfiguration</span><span class="pi">:</span>
  <span class="na">ChunkingStrategy</span><span class="pi">:</span> <span class="s">FIXED_SIZE</span>
  <span class="na">FixedSizeChunkingConfiguration</span><span class="pi">:</span>
    <span class="na">MaxTokens</span><span class="pi">:</span> <span class="m">300</span>              <span class="c1"># Max chunk size</span>
    <span class="na">OverlapPercentage</span><span class="pi">:</span> <span class="m">20</span>       <span class="c1"># 20% overlap between chunks</span>
</code></pre></div></div>

<p>How it works:</p>
<ul>
  <li>Document is tokenized using the embedding model’s tokenizer</li>
  <li>Split into chunks of 300 tokens</li>
  <li>Each chunk overlaps with the next by 20%</li>
  <li>This overlap ensures context isn’t lost at chunk boundaries</li>
</ul>

<h3 id="hierarchical-chunking">Hierarchical Chunking</h3>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">ChunkingConfiguration</span><span class="pi">:</span>
  <span class="na">ChunkingStrategy</span><span class="pi">:</span> <span class="s">HIERARCHICAL</span>
  <span class="na">HierarchicalChunkingConfiguration</span><span class="pi">:</span>
    <span class="na">LevelConfigurations</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">MaxTokens</span><span class="pi">:</span> <span class="m">1500</span>          <span class="c1"># Parent chunk size</span>
      <span class="pi">-</span> <span class="na">MaxTokens</span><span class="pi">:</span> <span class="m">300</span>           <span class="c1"># Child chunk size</span>
    <span class="na">OverlapTokens</span><span class="pi">:</span> <span class="m">60</span>            <span class="c1"># Absolute overlap (not percentage)</span>
</code></pre></div></div>

<p>How it works:</p>
<ul>
  <li>Document split into parent chunks (1500 tokens)</li>
  <li>Each parent split into child chunks (300 tokens)</li>
  <li>Child chunks overlap by 60 tokens</li>
  <li>Both parent and child chunks are embedded and stored</li>
  <li>Retrieval can leverage both granularities</li>
</ul>

<p>This preserves document structure better than fixed-size. When searching, you get:</p>
<ul>
  <li>High-precision matches from child chunks</li>
  <li>Broader context from parent chunks</li>
</ul>

<h3 id="semantic-chunking">Semantic Chunking</h3>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">ChunkingConfiguration</span><span class="pi">:</span>
  <span class="na">ChunkingStrategy</span><span class="pi">:</span> <span class="s">SEMANTIC</span>
  <span class="na">SemanticChunkingConfiguration</span><span class="pi">:</span>
    <span class="na">MaxTokens</span><span class="pi">:</span> <span class="m">300</span>                           <span class="c1"># Maximum chunk size</span>
    <span class="na">BufferSize</span><span class="pi">:</span> <span class="m">1</span>                            <span class="c1"># Sentences to buffer</span>
    <span class="na">BreakpointPercentileThreshold</span><span class="pi">:</span> <span class="m">95</span>        <span class="c1"># Similarity threshold</span>
</code></pre></div></div>

<p>How it works (this is the most sophisticated):</p>
<ul>
  <li>Document split into sentences</li>
  <li>Sentences embedded using the model</li>
  <li>Calculate cosine similarity between adjacent sentence embeddings</li>
  <li>When similarity drops below the 95th percentile threshold, create a chunk boundary</li>
  <li>This creates “natural” chunks based on semantic shifts in content</li>
  <li><code class="language-plaintext highlighter-rouge">BufferSize: 1</code> means look at 1 sentence on either side for context</li>
</ul>

<p>The result: chunks that respect topic boundaries rather than arbitrary token counts. A long paragraph discussing a single concept stays together, while a transition to a new topic creates a boundary even mid-paragraph.</p>

<h3 id="no-chunking">No Chunking</h3>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">ChunkingConfiguration</span><span class="pi">:</span>
  <span class="na">ChunkingStrategy</span><span class="pi">:</span> <span class="s">NONE</span>
</code></pre></div></div>

<p>The entire document is embedded as one unit. This is practical for:</p>
<ul>
  <li>Short documents</li>
  <li>When you need complete document context</li>
  <li>When document structure itself is important</li>
</ul>

<h2 id="supported-file-formats">Supported File Formats</h2>

<p>Before diving into the implementation details, it’s important to understand what types of documents you can use with Bedrock Knowledge Bases. The service supports following formats at time of writing:</p>

<p><strong>Text-Based Documents:</strong></p>
<ul>
  <li>PDF (<code class="language-plaintext highlighter-rouge">.pdf</code>) - with support for multimodal parsing of figures, charts, and tables</li>
  <li>Microsoft Word (<code class="language-plaintext highlighter-rouge">.doc</code>, <code class="language-plaintext highlighter-rouge">.docx</code>)</li>
  <li>Microsoft Excel (<code class="language-plaintext highlighter-rouge">.xls</code>, <code class="language-plaintext highlighter-rouge">.xlsx</code>)</li>
  <li>Plain text (<code class="language-plaintext highlighter-rouge">.txt</code>)</li>
  <li>Markdown (<code class="language-plaintext highlighter-rouge">.md</code>)</li>
  <li>HTML (<code class="language-plaintext highlighter-rouge">.html</code>)</li>
  <li>CSV (<code class="language-plaintext highlighter-rouge">.csv</code>) - supports one content field with metadata fields</li>
</ul>

<p><strong>Multimodal Content:</strong></p>
<ul>
  <li>Images: JPEG (<code class="language-plaintext highlighter-rouge">.jpeg</code>) and PNG (<code class="language-plaintext highlighter-rouge">.png</code>) - maximum 3.75 MB per file</li>
  <li>Audio files (when using S3 or custom data sources)</li>
  <li>Video files (when using S3 or custom data sources)</li>
</ul>

<p><strong>File Size Limits:</strong></p>
<ul>
  <li>General documents: maximum 50 MB per file</li>
  <li>Image files: maximum 3.75 MB per file</li>
</ul>

<p>For the complete and up-to-date list of supported formats and configurations, refer to the <a href="https://docs.aws.amazon.com/bedrock/latest/userguide/knowledge-base-ds.html">Prerequisites for your Amazon Bedrock knowledge base data</a> documentation.</p>

<h2 id="knowledge-base-sync">Knowledge Base Sync</h2>
<p>Here’s where we go beyond what the console offers. The console doesn’t provide automatic synchronization—you must manually trigger ingestion jobs.
When documents change frequently, this is impractical. Instead you should be able to upload documents to S3 and after a short moment knowledge base is updated automatically.
And while doing this, avoid running sync for every document separately as update can be the most costly operation as it triggers re-embedding of documents, which incurs model
invocation costs.”</p>

<h3 id="the-event-flow-in-detail">The Event Flow in Detail</h3>

<p><strong>Step 1: S3 Event Configuration</strong></p>

<p>First, the S3 bucket must enable Amazon EventBridge notifications:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">DataSourceBucket</span><span class="pi">:</span>
  <span class="na">Type</span><span class="pi">:</span> <span class="s">AWS::S3::Bucket</span>
  <span class="na">Condition</span><span class="pi">:</span> <span class="s">CreateNewBucket</span>
  <span class="na">Properties</span><span class="pi">:</span>
    <span class="na">NotificationConfiguration</span><span class="pi">:</span>
      <span class="na">EventBridgeConfiguration</span><span class="pi">:</span>
        <span class="na">EventBridgeEnabled</span><span class="pi">:</span> <span class="kc">true</span>
</code></pre></div></div>

<p>When enabled, S3 emits events to EventBridge for:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">Object Created</code> (PutObject, CompleteMultipartUpload, CopyObject, POST object)</li>
  <li><code class="language-plaintext highlighter-rouge">Object Deleted</code> (DeleteObject, DeleteObjects)</li>
</ul>

<p><strong>Step 2: EventBridge Rule</strong></p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">S3EventRule</span><span class="pi">:</span>
  <span class="na">Type</span><span class="pi">:</span> <span class="s">AWS::Events::Rule</span>
  <span class="na">Condition</span><span class="pi">:</span> <span class="s">AutoSyncEnabled</span>
  <span class="na">Properties</span><span class="pi">:</span>
    <span class="na">EventPattern</span><span class="pi">:</span>
      <span class="na">source</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="s">aws.s3</span>
      <span class="na">detail-type</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="s">Object Created</span>
        <span class="pi">-</span> <span class="s">Object Deleted</span>
      <span class="na">detail</span><span class="pi">:</span>
        <span class="na">bucket</span><span class="pi">:</span>
          <span class="na">name</span><span class="pi">:</span>
            <span class="pi">-</span> <span class="kt">!If</span> <span class="pi">[</span><span class="nv">CreateNewBucket</span><span class="pi">,</span> <span class="kt">!Ref</span> <span class="nv">DataSourceBucket</span><span class="pi">,</span> <span class="kt">!Ref</span> <span class="nv">ExistingDataSourceBucket</span><span class="pi">]</span>
    <span class="na">Targets</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">Arn</span><span class="pi">:</span> <span class="kt">!GetAtt</span> <span class="s">SyncEventQueue.Arn</span>
        <span class="na">Id</span><span class="pi">:</span> <span class="s">SQSTarget</span>
</code></pre></div></div>

<p>This rule filters ALL S3 events in your account to only:</p>
<ul>
  <li>Events from S3 (<code class="language-plaintext highlighter-rouge">source: aws.s3</code>)</li>
  <li>Creation or deletion events (<code class="language-plaintext highlighter-rouge">detail-type</code>)</li>
  <li>From your specific data source bucket (<code class="language-plaintext highlighter-rouge">detail.bucket.name</code>)</li>
</ul>

<p>Events matching this pattern are sent to the SQS queue.</p>

<p><strong>Step 3: Amazon Simple Queue Services (SQS) Batching Configuration</strong></p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">SyncEventQueue</span><span class="pi">:</span>
  <span class="na">Type</span><span class="pi">:</span> <span class="s">AWS::SQS::Queue</span>
  <span class="na">Condition</span><span class="pi">:</span> <span class="s">AutoSyncEnabled</span>
  <span class="na">Properties</span><span class="pi">:</span>
    <span class="na">MessageRetentionPeriod</span><span class="pi">:</span> <span class="m">86400</span>              <span class="c1"># 1 day</span>
    <span class="na">VisibilityTimeout</span><span class="pi">:</span> <span class="m">360</span>                     <span class="c1"># 6 minutes</span>
</code></pre></div></div>

<p>The Lambda event source mapping configures batching:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Events</span><span class="pi">:</span>
  <span class="na">SQSEvent</span><span class="pi">:</span>
    <span class="na">Type</span><span class="pi">:</span> <span class="s">SQS</span>
    <span class="na">Properties</span><span class="pi">:</span>
      <span class="na">Queue</span><span class="pi">:</span> <span class="kt">!GetAtt</span> <span class="s">SyncEventQueue.Arn</span>
      <span class="na">BatchSize</span><span class="pi">:</span> <span class="m">100</span>                           <span class="c1"># Process up to 100 events</span>
      <span class="na">MaximumBatchingWindowInSeconds</span><span class="pi">:</span> <span class="m">60</span>       <span class="c1"># Wait up to 60s to accumulate</span>
</code></pre></div></div>

<p>This batching is critical for efficiency:</p>
<ul>
  <li>If you upload 1 file, Lambda triggers after 60 seconds with 1 event</li>
  <li>If you upload 50 files within 60 seconds, Lambda triggers once with 50 events</li>
  <li>If you upload 100+ files, Lambda triggers with 100 events (max batch)</li>
</ul>

<p><strong>Step 4: AWS Lambda Processing Logic</strong></p>

<p>The Lambda function implements intelligent sync management. Let’s examine the key parts:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">lambda_handler</span><span class="p">(</span><span class="n">event</span><span class="p">,</span> <span class="n">context</span><span class="p">):</span>
    <span class="n">num_records</span> <span class="o">=</span> <span class="nf">len</span><span class="p">(</span><span class="n">event</span><span class="p">.</span><span class="nf">get</span><span class="p">(</span><span class="sh">'</span><span class="s">Records</span><span class="sh">'</span><span class="p">,</span> <span class="p">[]))</span>
    <span class="nf">print</span><span class="p">(</span><span class="sa">f</span><span class="sh">"</span><span class="s">Received </span><span class="si">{</span><span class="n">num_records</span><span class="si">}</span><span class="s"> event(s)</span><span class="sh">"</span><span class="p">)</span>

    <span class="c1"># Check if there's already an ingestion job running
</span>    <span class="n">response</span> <span class="o">=</span> <span class="n">bedrock_agent</span><span class="p">.</span><span class="nf">list_ingestion_jobs</span><span class="p">(</span>
        <span class="n">knowledgeBaseId</span><span class="o">=</span><span class="n">KNOWLEDGE_BASE_ID</span><span class="p">,</span>
        <span class="n">dataSourceId</span><span class="o">=</span><span class="n">DATA_SOURCE_ID</span><span class="p">,</span>
        <span class="n">maxResults</span><span class="o">=</span><span class="mi">1</span>
    <span class="p">)</span>

    <span class="n">ingestion_jobs</span> <span class="o">=</span> <span class="n">response</span><span class="p">.</span><span class="nf">get</span><span class="p">(</span><span class="sh">'</span><span class="s">ingestionJobSummaries</span><span class="sh">'</span><span class="p">,</span> <span class="p">[])</span>

    <span class="k">if</span> <span class="n">ingestion_jobs</span><span class="p">:</span>
        <span class="n">latest_job</span> <span class="o">=</span> <span class="n">ingestion_jobs</span><span class="p">[</span><span class="mi">0</span><span class="p">]</span>
        <span class="n">status</span> <span class="o">=</span> <span class="n">latest_job</span><span class="p">.</span><span class="nf">get</span><span class="p">(</span><span class="sh">'</span><span class="s">status</span><span class="sh">'</span><span class="p">)</span>

        <span class="k">if</span> <span class="n">status</span> <span class="ow">in</span> <span class="p">[</span><span class="sh">'</span><span class="s">STARTING</span><span class="sh">'</span><span class="p">,</span> <span class="sh">'</span><span class="s">IN_PROGRESS</span><span class="sh">'</span><span class="p">]:</span>
            <span class="c1"># Sync is running - schedule a follow-up
</span>            <span class="n">sqs</span><span class="p">.</span><span class="nf">send_message</span><span class="p">(</span>
                <span class="n">QueueUrl</span><span class="o">=</span><span class="n">SYNC_QUEUE_URL</span><span class="p">,</span>
                <span class="n">MessageBody</span><span class="o">=</span><span class="n">json</span><span class="p">.</span><span class="nf">dumps</span><span class="p">({</span>
                    <span class="sh">'</span><span class="s">type</span><span class="sh">'</span><span class="p">:</span> <span class="sh">'</span><span class="s">retry</span><span class="sh">'</span><span class="p">,</span>
                    <span class="sh">'</span><span class="s">reason</span><span class="sh">'</span><span class="p">:</span> <span class="sh">'</span><span class="s">sync_in_progress</span><span class="sh">'</span><span class="p">,</span>
                    <span class="sh">'</span><span class="s">timestamp</span><span class="sh">'</span><span class="p">:</span> <span class="n">datetime</span><span class="p">.</span><span class="nf">now</span><span class="p">(</span><span class="n">timezone</span><span class="p">.</span><span class="n">utc</span><span class="p">).</span><span class="nf">isoformat</span><span class="p">()</span>
                <span class="p">}),</span>
                <span class="n">DelaySeconds</span><span class="o">=</span><span class="mi">300</span>  <span class="c1"># Retry after 5 minutes
</span>            <span class="p">)</span>
            <span class="k">return</span> <span class="p">{</span><span class="sh">'</span><span class="s">statusCode</span><span class="sh">'</span><span class="p">:</span> <span class="mi">200</span><span class="p">,</span> <span class="sh">'</span><span class="s">body</span><span class="sh">'</span><span class="p">:</span> <span class="sh">'</span><span class="s">Sync deferred</span><span class="sh">'</span><span class="p">}</span>
</code></pre></div></div>

<p><strong>Why check for running jobs?</strong> Bedrock ingestion jobs can take several minutes. If we start a new job while one is running, we waste resources and create race conditions.</p>

<p><strong>Why send a retry message?</strong> Files added during a sync won’t be in the current job. The retry message ensures a follow-up sync happens after the current one completes.</p>

<p><strong>Why 5-minute delay?</strong> This prevents busy-waiting. The Lambda won’t be triggered by the retry message until 5 minutes pass, by which time most syncs have completed.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code>    <span class="c1"># No running job - check if queue needs purging
</span>    <span class="n">queue_attrs</span> <span class="o">=</span> <span class="n">sqs</span><span class="p">.</span><span class="nf">get_queue_attributes</span><span class="p">(</span>
        <span class="n">QueueUrl</span><span class="o">=</span><span class="n">SYNC_QUEUE_URL</span><span class="p">,</span>
        <span class="n">AttributeNames</span><span class="o">=</span><span class="p">[</span><span class="sh">'</span><span class="s">ApproximateNumberOfMessages</span><span class="sh">'</span><span class="p">,</span>
                        <span class="sh">'</span><span class="s">ApproximateNumberOfMessagesDelayed</span><span class="sh">'</span><span class="p">]</span>
    <span class="p">)</span>

    <span class="n">total_messages</span> <span class="o">=</span> <span class="p">(</span>
        <span class="nf">int</span><span class="p">(</span><span class="n">queue_attrs</span><span class="p">[</span><span class="sh">'</span><span class="s">Attributes</span><span class="sh">'</span><span class="p">][</span><span class="sh">'</span><span class="s">ApproximateNumberOfMessages</span><span class="sh">'</span><span class="p">])</span> <span class="o">+</span>
        <span class="nf">int</span><span class="p">(</span><span class="n">queue_attrs</span><span class="p">[</span><span class="sh">'</span><span class="s">Attributes</span><span class="sh">'</span><span class="p">][</span><span class="sh">'</span><span class="s">ApproximateNumberOfMessagesDelayed</span><span class="sh">'</span><span class="p">])</span>
    <span class="p">)</span>

    <span class="k">if</span> <span class="n">total_messages</span> <span class="o">&gt;</span> <span class="mi">0</span><span class="p">:</span>
        <span class="k">try</span><span class="p">:</span>
            <span class="n">sqs</span><span class="p">.</span><span class="nf">purge_queue</span><span class="p">(</span><span class="n">QueueUrl</span><span class="o">=</span><span class="n">SYNC_QUEUE_URL</span><span class="p">)</span>
            <span class="nf">print</span><span class="p">(</span><span class="sa">f</span><span class="sh">"</span><span class="s">Purged </span><span class="si">{</span><span class="n">total_messages</span><span class="si">}</span><span class="s"> messages from queue</span><span class="sh">"</span><span class="p">)</span>
        <span class="k">except</span> <span class="n">ClientError</span> <span class="k">as</span> <span class="n">e</span><span class="p">:</span>
            <span class="k">if</span> <span class="sh">'</span><span class="s">PurgeQueueInProgress</span><span class="sh">'</span> <span class="ow">in</span> <span class="nf">str</span><span class="p">(</span><span class="n">e</span><span class="p">):</span>
                <span class="nf">print</span><span class="p">(</span><span class="sh">"</span><span class="s">Queue purge already in progress, continuing with sync</span><span class="sh">"</span><span class="p">)</span>
</code></pre></div></div>

<p><strong>Why purge the queue?</strong> This is non-obvious but critical. When Bedrock starts an ingestion job, it scans the ENTIRE S3 bucket. Individual S3 event messages telling us “file X was added” become redundant — we’re processing ALL files anyway.</p>

<p>Without purging:</p>
<ul>
  <li>Queue accumulates thousands of S3 event messages</li>
  <li>Retry messages keep accumulating during long syncs</li>
  <li>Lambda gets triggered repeatedly with redundant batches</li>
</ul>

<p>With purging:</p>
<ul>
  <li>Before each sync, we clear all queued messages</li>
  <li>The sync processes everything in the bucket</li>
  <li>Clean slate for the next round of events</li>
</ul>

<p><strong>Why check message count first?</strong> SQS enforces a 60-second cooldown between purge operations. If we purge an empty queue, we can’t purge again for 60 seconds. By checking first, we only purge when necessary.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code>    <span class="c1"># Start the ingestion job
</span>    <span class="n">response</span> <span class="o">=</span> <span class="n">bedrock_agent</span><span class="p">.</span><span class="nf">start_ingestion_job</span><span class="p">(</span>
        <span class="n">knowledgeBaseId</span><span class="o">=</span><span class="n">KNOWLEDGE_BASE_ID</span><span class="p">,</span>
        <span class="n">dataSourceId</span><span class="o">=</span><span class="n">DATA_SOURCE_ID</span>
    <span class="p">)</span>

    <span class="n">job_id</span> <span class="o">=</span> <span class="n">response</span><span class="p">[</span><span class="sh">'</span><span class="s">ingestionJob</span><span class="sh">'</span><span class="p">][</span><span class="sh">'</span><span class="s">ingestionJobId</span><span class="sh">'</span><span class="p">]</span>
    <span class="nf">print</span><span class="p">(</span><span class="sa">f</span><span class="sh">"</span><span class="s">Started ingestion job: </span><span class="si">{</span><span class="n">job_id</span><span class="si">}</span><span class="sh">"</span><span class="p">)</span>

    <span class="k">return</span> <span class="p">{</span>
        <span class="sh">'</span><span class="s">statusCode</span><span class="sh">'</span><span class="p">:</span> <span class="mi">200</span><span class="p">,</span>
        <span class="sh">'</span><span class="s">body</span><span class="sh">'</span><span class="p">:</span> <span class="n">json</span><span class="p">.</span><span class="nf">dumps</span><span class="p">({</span>
            <span class="sh">'</span><span class="s">message</span><span class="sh">'</span><span class="p">:</span> <span class="sh">'</span><span class="s">Ingestion job started</span><span class="sh">'</span><span class="p">,</span>
            <span class="sh">'</span><span class="s">jobId</span><span class="sh">'</span><span class="p">:</span> <span class="n">job_id</span>
        <span class="p">})</span>
    <span class="p">}</span>
</code></pre></div></div>

<p>The ingestion job processes:</p>
<ul>
  <li>All objects in the S3 data source bucket</li>
  <li>Applies the configured chunking strategy</li>
  <li>Generates embeddings via the embedding model</li>
  <li>Stores vectors in the vector storage bucket</li>
  <li>Updates the searchable index</li>
</ul>

<h3 id="concurrency-control">Concurrency Control</h3>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">AutoSyncFunction</span><span class="pi">:</span>
  <span class="na">Type</span><span class="pi">:</span> <span class="s">AWS::Serverless::Function</span>
  <span class="na">Properties</span><span class="pi">:</span>
    <span class="na">ReservedConcurrentExecutions</span><span class="pi">:</span> <span class="m">1</span>    <span class="c1"># Only 1 instance can run at a time</span>
</code></pre></div></div>

<p>This setting is critical. Without it multiple batches of S3 events could trigger multiple Lambda instances. Each instance might call <code class="language-plaintext highlighter-rouge">list_ingestion_jobs</code> and see “no running job”.
Multiple instances start duplicate ingestion jobs simultaneously causing wasted resources and potential race conditions.</p>

<h3 id="edge-cases-handled">Edge Cases Handled</h3>

<h4 id="fast-consecutive-syncs">Fast consecutive syncs</h4>
<p>If your documents are small and ingestion completes in &lt;60 seconds:</p>
<ul>
  <li>New files trigger Lambda</li>
  <li>Check finds no running job</li>
  <li>Check message count (might be 0 if queue was just purged)</li>
  <li>Skip purge (avoids 60-second cooldown violation)</li>
  <li>Start new sync</li>
</ul>

<h4 id="purge-failure-during-long-sync">Purge failure during long sync</h4>
<p>If files keep arriving during a 5-minute sync:</p>
<ul>
  <li>Multiple Lambda invocations send retry messages</li>
  <li>Eventually, retry delay expires and Lambda runs</li>
  <li>Tries to purge queue</li>
  <li>Purge fails due to SQS’s 60-second cooldown from previous purge.</li>
  <li>Lambda logs warning and continues anyway</li>
  <li>Sync still succeeds (graceful degradation)</li>
</ul>

<h4 id="sync-completes-during-retry-delay">Sync completes during retry delay</h4>
<p>Upload 100 files, sync takes 3 minutes:</p>
<ul>
  <li>During those 3 minutes, new S3 events trigger Lambda</li>
  <li>Each batch schedules a 5-minute retry</li>
  <li>After 3 minutes, sync completes</li>
  <li>At 5 minutes, first retry message triggers Lambda</li>
  <li>No job running, queue is purged, new sync starts</li>
  <li>Subsequent retry messages are purged before they trigger (redundant but harmless)</li>
</ul>

<h2 id="deployment">Deployment</h2>

<p>Let’s walk through deployment and observe what gets created.</p>

<h3 id="deploy-with-new-bucket">Deploy with New Bucket</h3>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>aws cloudformation deploy <span class="se">\</span>
  <span class="nt">--template-file</span> template.yaml <span class="se">\</span>
  <span class="nt">--stack-name</span> my-knowledge-base <span class="se">\</span>
  <span class="nt">--parameter-overrides</span> <span class="se">\</span>
    <span class="nv">KnowledgeBaseName</span><span class="o">=</span>MyKnowledgeBase <span class="se">\</span>
    <span class="nv">ChunkingStrategy</span><span class="o">=</span>SEMANTIC <span class="se">\</span>
    <span class="nv">EnableAutoSync</span><span class="o">=</span><span class="nb">true</span> <span class="se">\</span>
    <span class="nv">AutoSyncDelaySeconds</span><span class="o">=</span>60 <span class="se">\</span>
  <span class="nt">--capabilities</span> CAPABILITY_NAMED_IAM
</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">CAPABILITY_NAMED_IAM</code> flag is required because the template creates IAM roles with custom names. This is CloudFormation’s safety mechanism—you must explicitly acknowledge that you’re creating IAM resources.</p>

<p>Watch the stack events:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>aws cloudformation describe-stack-events <span class="se">\</span>
  <span class="nt">--stack-name</span> my-knowledge-base <span class="se">\</span>
  <span class="nt">--max-items</span> 20
</code></pre></div></div>

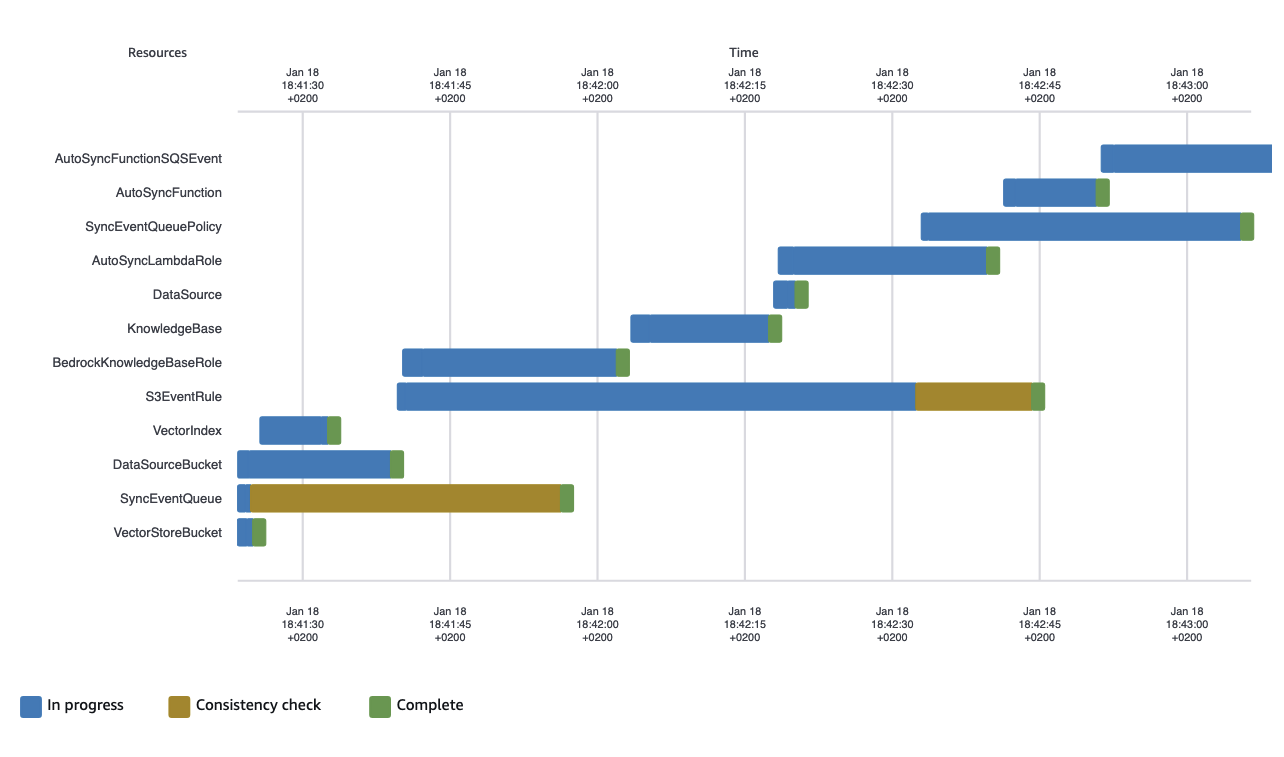
<p>You’ll see resources created in dependency order</p>

<p><a href="/img/bedrock-kb-s3/deployment.png"><img src="/img/bedrock-kb-s3/deployment.png" width="100%" /></a></p>

<h3 id="upload-documents-and-observe">Upload Documents and Observe</h3>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Get bucket name from stack output</span>
<span class="nv">BUCKET_NAME</span><span class="o">=</span><span class="si">$(</span>aws cloudformation describe-stacks <span class="se">\</span>
  <span class="nt">--stack-name</span> my-knowledge-base <span class="se">\</span>
  <span class="nt">--query</span> <span class="s1">'Stacks[0].Outputs[?OutputKey==`DataSourceBucketName`].OutputValue'</span> <span class="se">\</span>
  <span class="nt">--output</span> text<span class="si">)</span>

<span class="c"># Upload a document</span>
aws s3 <span class="nb">cp </span>my-document.pdf s3://<span class="k">${</span><span class="nv">BUCKET_NAME</span><span class="k">}</span>/
</code></pre></div></div>

<p>Now watch the auto-sync in action:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Get Lambda function name</span>
<span class="nv">FUNCTION_NAME</span><span class="o">=</span><span class="si">$(</span>aws cloudformation describe-stacks <span class="se">\</span>
  <span class="nt">--stack-name</span> my-knowledge-base <span class="se">\</span>
  <span class="nt">--query</span> <span class="s1">'Stacks[0].Outputs[?OutputKey==`AutoSyncFunctionArn`].OutputValue'</span> <span class="se">\</span>
  <span class="nt">--output</span> text | <span class="nb">cut</span> <span class="nt">-d</span>: <span class="nt">-f7</span><span class="si">)</span>

<span class="c"># Tail logs</span>
aws logs <span class="nb">tail</span> /aws/lambda/<span class="k">${</span><span class="nv">FUNCTION_NAME</span><span class="k">}</span> <span class="nt">--follow</span>
</code></pre></div></div>

<p>You’ll see output like:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>2026-01-18T13:45:23.456Z START RequestId: abc-123-def
2026-01-18T13:45:23.789Z Received 1 event(s)
2026-01-18T13:45:24.123Z Latest ingestion job xyz-789 status: COMPLETE
2026-01-18T13:45:24.456Z Queue has 0 messages, skipping purge
2026-01-18T13:45:25.789Z Started ingestion job: new-job-456
2026-01-18T13:45:25.890Z END RequestId: abc-123-def
</code></pre></div></div>

<p>Check the ingestion job status:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">KB_ID</span><span class="o">=</span><span class="si">$(</span>aws cloudformation describe-stacks <span class="se">\</span>
  <span class="nt">--stack-name</span> my-knowledge-base <span class="se">\</span>
  <span class="nt">--query</span> <span class="s1">'Stacks[0].Outputs[?OutputKey==`KnowledgeBaseId`].OutputValue'</span> <span class="se">\</span>
  <span class="nt">--output</span> text<span class="si">)</span>

<span class="nv">DS_ID</span><span class="o">=</span><span class="si">$(</span>aws cloudformation describe-stacks <span class="se">\</span>
  <span class="nt">--stack-name</span> my-knowledge-base <span class="se">\</span>
  <span class="nt">--query</span> <span class="s1">'Stacks[0].Outputs[?OutputKey==`DataSourceId`].OutputValue'</span> <span class="se">\</span>
  <span class="nt">--output</span> text<span class="si">)</span>

aws bedrock-agent list-ingestion-jobs <span class="se">\</span>
  <span class="nt">--knowledge-base-id</span> <span class="k">${</span><span class="nv">KB_ID</span><span class="k">}</span> <span class="se">\</span>
  <span class="nt">--data-source-id</span> <span class="k">${</span><span class="nv">DS_ID</span><span class="k">}</span> <span class="se">\</span>
  <span class="nt">--max-results</span> 5
</code></pre></div></div>

<p>Output shows the job lifecycle:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"ingestionJobSummaries"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
    </span><span class="p">{</span><span class="w">
      </span><span class="nl">"ingestionJobId"</span><span class="p">:</span><span class="w"> </span><span class="s2">"new-job-456"</span><span class="p">,</span><span class="w">
      </span><span class="nl">"status"</span><span class="p">:</span><span class="w"> </span><span class="s2">"IN_PROGRESS"</span><span class="p">,</span><span class="w">
      </span><span class="nl">"startedAt"</span><span class="p">:</span><span class="w"> </span><span class="s2">"2026-01-18T13:45:25Z"</span><span class="p">,</span><span class="w">
      </span><span class="nl">"statistics"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
        </span><span class="nl">"numberOfDocumentsScanned"</span><span class="p">:</span><span class="w"> </span><span class="mi">1</span><span class="p">,</span><span class="w">
        </span><span class="nl">"numberOfNewDocumentsIndexed"</span><span class="p">:</span><span class="w"> </span><span class="mi">0</span><span class="p">,</span><span class="w">
        </span><span class="nl">"numberOfModifiedDocumentsIndexed"</span><span class="p">:</span><span class="w"> </span><span class="mi">1</span><span class="w">
      </span><span class="p">}</span><span class="w">
    </span><span class="p">}</span><span class="w">
  </span><span class="p">]</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>Wait a few minutes and query again—status changes to <code class="language-plaintext highlighter-rouge">COMPLETE</code>.</p>

<h2 id="lessons-from-building-this">Lessons from Building This</h2>

<h4 id="the-iam-trust-policy-conditions-matter">The IAM Trust Policy Conditions Matter</h4>

<p>The Condition in the Knowledge Base role’s trust policy is important.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Condition</span><span class="pi">:</span>
  <span class="na">StringEquals</span><span class="pi">:</span>
    <span class="na">aws:SourceAccount</span><span class="pi">:</span> <span class="kt">!Ref</span> <span class="s">AWS::AccountId</span>
</code></pre></div></div>

<p>Without this, the role could potentially be assumed by Bedrock from ANY AWS account. Always scope trust policies to your account and specific resource ARNs.</p>

<h4 id="eventbridge-must-be-explicitly-enabled">EventBridge Must Be Explicitly Enabled</h4>

<p>S3 doesn’t emit EventBridge events by default—you must enable it:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">NotificationConfiguration</span><span class="pi">:</span>
  <span class="na">EventBridgeConfiguration</span><span class="pi">:</span>
    <span class="na">EventBridgeEnabled</span><span class="pi">:</span> <span class="kc">true</span>
</code></pre></div></div>

<p>For existing buckets, you must enable this manually as CloudFormation can not modify resources that are not part of the stack.</p>

<h4 id="queue-purging-prevents-message-accumulation">Queue Purging Prevents Message Accumulation</h4>

<p>Without the purge logic, the queue accumulated thousands of messages during testing. Each S3 upload creates an event, and during long syncs, retry messages keep piling up. The purge ensures clean state.</p>

<h4 id="concurrency-limit-is-critical">Concurrency Limit is Critical</h4>

<p>When I initially tested without <code class="language-plaintext highlighter-rouge">ReservedConcurrentExecutions: 1</code>, multiple Lambda instances started duplicate ingestion jobs. The concurrency limit ensures sequential execution and prevents race conditions.</p>

<h4 id="semantic-chunking-requires-careful-tuning">Semantic Chunking Requires Careful Tuning</h4>

<p>Semantic chunking with default thresholds created very large chunks (800+ tokens) for some documents. Tuning <code class="language-plaintext highlighter-rouge">BreakpointPercentileThreshold</code> from 95 to 90 created more appropriately-sized chunks. The “right” value depends on your document characteristics.</p>

<h4 id="eventual-consistency">Eventual Consistency</h4>

<p>After starting an ingestion job, it takes a few seconds for <code class="language-plaintext highlighter-rouge">list_ingestion_jobs</code> to reflect the new job. During that window, another Lambda invocation might see “no running job” and start a duplicate. The concurrency limit prevents this race condition.</p>

<h2 id="with-little-help-from-llm">With Little Help from LLM</h2>

<p>Building this template wasn’t a solo effort — I used an LLM to accelerate development. The process revealed both the power and limitations of AI-assisted infrastructure coding.</p>

<h4 id="the-initial-prompt">The Initial Prompt</h4>

<p>I started simple:</p>

<blockquote>
  <p>“Create CloudFormation template that creates bedrock knowledge base using s3 vector and all supporting resources and configurations required”</p>
</blockquote>

<p>The LLM generated a complete template within seconds. Impressive… until I looked closer at the generated code and comments. The solution was using OpenSearch, not S3 Vector storage.
This is typical with new technology. S3 Vector support for Bedrock Knowledge Bases became generally available in December 2024—very recent.
The LLM’s training data contains far more examples of the previous generation solution (OpenSearch Serverless) than the newer S3 Vector approach.
When you ask for “bedrock knowledge base,” the model defaults to the pattern it’s seen most often and might ignore some of your instructions.</p>

<h4 id="the-correction-cycle">The Correction Cycle</h4>

<p>I followed up with a clarification:</p>

<blockquote>
  <p>“I don’t want to use opensearch but S3 Vector bucket”</p>
</blockquote>

<p>The LLM responded enthusiastically: “This is much simpler and uses fully managed services without the need for OpenSearch!”
That was exactly my point—S3 Vector eliminates the complexity of managing OpenSearch clusters.
But when I validated the template with <code class="language-plaintext highlighter-rouge">aws cloudformation validate-template</code>, problems emerged.
The storage configuration was incomplete.</p>

<p>Another iteration:</p>

<blockquote>
  <p>“Storage configuration should be S3_VECTOR type and include configuration”</p>
</blockquote>

<p>The classic LLM response: “You’re absolutely right! …”</p>

<p>After this correction, I had a working first version. The entire process took maybe 15 minutes — much faster than writing from scratch, even for someone familiar with CloudFormation.</p>

<h4 id="what-the-llm-got-right">What the LLM Got Right</h4>

<p>The LLM excelled at:</p>

<ul>
  <li><strong>Boilerplate structure</strong>: Parameters, conditions, outputs etc.</li>
  <li><strong>IAM role scaffolding</strong>: Trust policies and basic permission structure</li>
  <li><strong>Resource dependencies</strong>: Using <code class="language-plaintext highlighter-rouge">!Ref</code> and <code class="language-plaintext highlighter-rouge">!GetAtt</code> correctly</li>
  <li><strong>Common patterns</strong>: S3 bucket configurations, Lambda function basics</li>
</ul>

<p>These are the tedious parts of CloudFormation development. Having them generated instantly let me focus on the interesting problems: auto-sync logic and edge case handling.</p>

<h4 id="what-required-human-expertise">What Required Human Expertise</h4>

<p>The LLM struggled with:</p>

<ul>
  <li><strong>New service features</strong>: S3 Vector configuration details weren’t in training data</li>
  <li><strong>Edge cases</strong>: Queue purging logic, concurrency limits, eventual consistency handling</li>
  <li><strong>Production patterns</strong>: Error handling, retry logic, graceful degradation</li>
</ul>

<p>The auto-sync mechanism—the most valuable part of this template—required human design. The LLM could generate a Lambda function that calls <code class="language-plaintext highlighter-rouge">start_ingestion_job</code>, 
but it didn’t consider on it’s own what happens when multiple S3 events arrive simultaneously, how to prevent duplicate ingestion jobs, or do optimization like
purging the queue or setting concurrency limit.</p>

<h2 id="conclusion">Conclusion</h2>

<p>This implementation achieves two complementary goals:</p>

<h4 id="demystifying-the-foundation">Demystifying the Foundation</h4>

<p>The AWS console makes it easy to create a Bedrock Knowledge Base—a few clicks and you’re done. But understanding what’s actually happening beneath that interface is essential for:</p>

<ul>
  <li><strong>Production deployments</strong>: You need to know IAM roles, permissions, and dependencies</li>
  <li><strong>Troubleshooting</strong>: When something breaks, you need to know which component failed</li>
  <li><strong>Customization</strong>: You can’t extend what you don’t understand</li>
  <li><strong>Cost optimization</strong>: You need to know what resources you’re paying for</li>
  <li><strong>Security</strong>: You must understand what permissions are granted and why</li>
</ul>

<p>By building this as CloudFormation, we’ve revealed every component, every permission, every dependency. The “magic” of the console becomes transparent, understandable infrastructure that you can reason about, modify, and confidently deploy to production.</p>

<h4 id="adding-the-right-kind-of-magic">Adding the Right Kind of Magic</h4>

<p>The auto-sync mechanism adds automation that works invisibly for end users (documents just sync automatically), remains transparent to developers (every trigger is explicit in code) and scales to zero when there are no document to process.</p>

<p>Whether you’re building a documentation search system, customer support chatbot, or legal research tool, this template provides a solid foundation: transparent enough to understand completely, automated enough to eliminate operational toil.</p>

<hr />]]></content><author><name>kallu</name></author><category term="aws" /><category term="s3" /><category term="vector" /><category term="bedrock" /><category term="knowledgebase" /><summary type="html"><![CDATA[This post demystifies the process of setting up S3 Vector as Bedrock Knowledge Base by walking through complete implementation in CloudFormation. Examining the infrastructure as code will reveal components, dependencies, and permissions required—bringing full transparency to the "magic" that happens when the same is build from AWS console.]]></summary></entry><entry><title type="html">If you must have NAT, make it regional</title><link href="https://carriagereturn.nl/aws/vpc/nat/regional/2025/11/23/regional-nat.html" rel="alternate" type="text/html" title="If you must have NAT, make it regional" /><published>2025-11-23T16:00:00+00:00</published><updated>2025-11-23T16:00:00+00:00</updated><id>https://carriagereturn.nl/aws/vpc/nat/regional/2025/11/23/regional-nat</id><content type="html" xml:base="https://carriagereturn.nl/aws/vpc/nat/regional/2025/11/23/regional-nat.html"><![CDATA[<p>Shortly after I published my post about how <a href="/aws/lambda/ipv6/vpc/nat/2025/11/16/lambda-ipv6-vpc.html">You don’t need NAT gateway to deploy Lambda into VPC</a>, Amazon Web Services (AWS) announced iAmazon VPC Regional NAT Gateway. Whilst IPv6 eliminates the need for NAT entirely, Regional NAT Gateway represents a major update to best practices for IPv4 Amazon Virtual Private Cloud (VPC) networking.</p>

<h2 id="brief-history-of-aws-nat-solutions">Brief History of AWS NAT Solutions</h2>

<p>First there were <a href="https://docs.aws.amazon.com/vpc/latest/userguide/work-with-nat-instances.html">NAT instances</a>. You’d spin up an Amazon Elastic Compute Cloud (EC2) instance with a special Amazon Machine Image (AMI), disable source/destination checks, point your route tables at it, and hope it didn’t fall over. Instance sizing, high availability, patching, monitoring - all yours to manage. It worked, but it was a high maintenance solution.</p>

<p>Late 2015 AWS announced <a href="https://aws.amazon.com/blogs/aws/new-managed-nat-network-address-translation-gateway-for-aws/">Amazon VPC NAT Gateway</a>. Fully managed, highly available, no patching required. Create it in a public subnet, add a route, job done.</p>

<p>In 2021 AWS added <a href="https://aws.amazon.com/about-aws/whats-new/2021/06/aws-removes-nat-gateways-dependence-on-internet-gateway-for-private-communications/">Private NAT Gateway</a> to the mix. This one isn’t for Internet access but for connecting VPCs and other networks when you’ve got overlapping CIDR ranges. I wrote about how this enables <a href="https://docs.aws.amazon.com/whitepapers/latest/building-scalable-secure-multi-vpc-network-infrastructure/private-nat-gateway.html">more agile networking</a> patterns that weren’t really feasible before.</p>

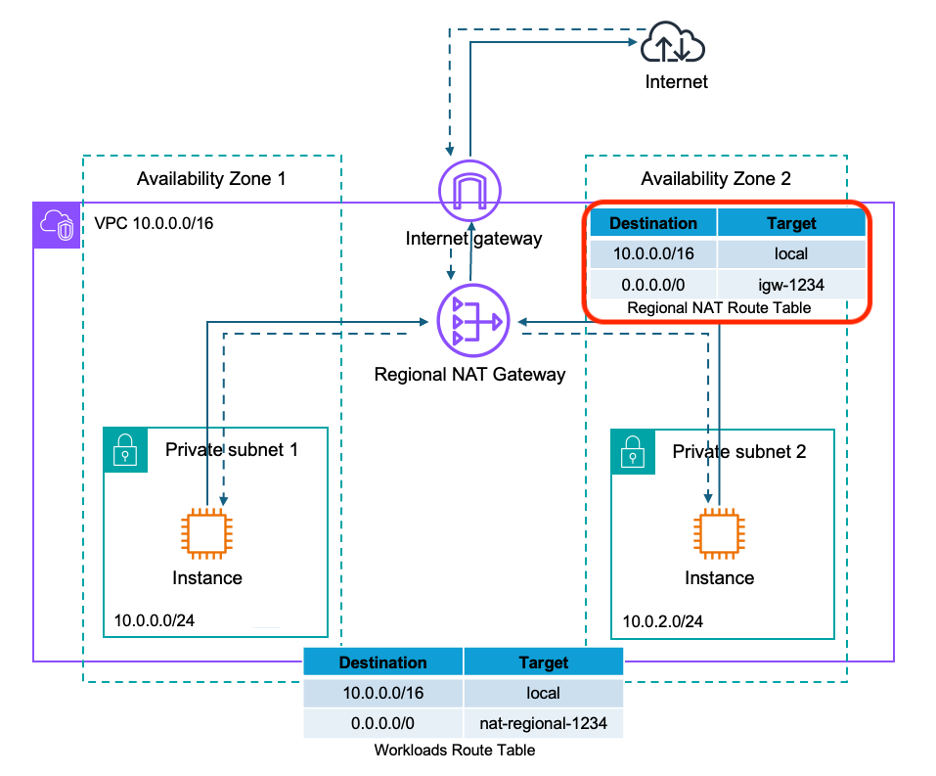
<p>And now, in November 2025, AWS announced <a href="https://aws.amazon.com/about-aws/whats-new/2025/11/aws-nat-gateway-regional-availability/">Amazon VPC Regional NAT Gateway</a>. Unlike traditional NAT Gateway that lives in a single Availability Zone (AZ), the regional variant spans multiple AZs. AWS handles the high availability and scaling for you.</p>

<h2 id="simpler">Simpler</h2>

<p>AWS services come in 3 flavours - <a href="https://docs.aws.amazon.com/whitepapers/latest/aws-fault-isolation-boundaries/zonal-services.html">zonal</a>, <a href="https://docs.aws.amazon.com/whitepapers/latest/aws-fault-isolation-boundaries/regional-services.html">regional</a> and <a href="https://docs.aws.amazon.com/whitepapers/latest/aws-fault-isolation-boundaries/global-services.html">global</a>. Zonal services live in a specific availability zone, whilst regional services span the entire region. And here’s the thing - they’re configured with network components that match their scope.</p>

<p>Classic NAT Gateway is a zonal service. You create it in a specific AZ, attach it to a subnet (which is also zonal), and it serves traffic for that AZ. If you want high availability, you must deploy another NAT Gateway in another AZ, with another subnet, and manage separate route tables for each AZ’s private subnets. It works, but you’re thinking about AZ topology every step.</p>

<p>Regional NAT Gateway makes this much simpler. It’s a regional service, so it attaches directly to your VPC that is a regional network construct. One NAT Gateway for the entire VPC, regardless of how many AZs you are using. Routing isn’t specific to availability zone any longer but works the same way as public subnets with an Internet Gateway. Just point the default route to the regional NAT Gateway and you’re done.</p>

<p><a href="/img/regional-nat/diagram.png"><img src="/img/regional-nat/diagram.png" hspace="20" width="90%" /></a></p>

<p>This is particularly nice if you don’t need any inbound connections from the Internet. Traditionally you’d still need public subnets for the NAT Gateways even though nothing was accepting inbound traffic. Now you can drop public subnets entirely and run a pure private subnet architecture. Simpler network topology, fewer moving parts.</p>

<p>Note there is one new component in above setup - the Regional NAT Route Table. It is created automatically with a pre-configured route to the Internet Gateway. But you can customize it to route to middleboxes like firewalls, enabling traffic inspection for outbound flows. See <a href="https://aws.amazon.com/blogs/networking-and-content-delivery/introducing-amazon-vpc-regional-nat-gateway/">AWS blog post</a> for more details.</p>

<p><em>NOTE:</em> If you read my previous post about <a href="/aws/lambda/ipv6/vpc/nat/2025/11/16/lambda-ipv6-vpc.html">Lambda and IPv6</a>, you might notice this looks very similar to IPv6 Egress Only Gateway. But you shouldn’t think Regional NAT gateway as IPv4 equivalent to IPv6 Egress gateway because it still does address translation that isn’t required when using IPv6.</p>

<h2 id="more-secure">More Secure</h2>

<p>Public subnets are where things with public IPs live - load balancers, <a href="/aws/ssh/ssm/2021/01/03/tunnel-into-vpc.html">bastion hosts</a>, anything that needs inbound connections from the Internet. If the only thing you have in public subnets are NAT gateways, then you don’t need them any more after switching to regional NAT gateway.</p>

<p>This matters for security because now you can’t expose something to the Internet by accident if there’s nowhere to expose it. No public subnets means no path for resources to get public IPs. Someone wants to make their database publicly accessible? Not happening - there is no subnet configuration that would allow it. It’s defence in depth through architectural constraint.</p>

<p>However, there is a small catch. You still need an Internet Gateway attached to your VPC. Regional NAT Gateway needs it for outbound connectivity, even though you’re not routing any traffic to it from your subnets. As the <a href="https://docs.aws.amazon.com/vpc/latest/userguide/nat-gateways-regional.html">AWS documentation</a> notes, when you create a regional NAT Gateway, AWS “automatically creates a route table for it, which comes with a pre-configured route to the internet gateway.” So the IGW must exist, but your private subnets never point routes to it.</p>

<h2 id="cheaper-">Cheaper (?)</h2>

<p>If you’re running traditional NAT Gateways in three AZs and thinking “brilliant, I’ll replace all three with one regional NAT Gateway and cut my costs by two-thirds” - this isn’t how it works :-(</p>

<p>Regional NAT Gateway pricing is per AZ, just like traditional NAT Gateway. The difference is it’s automatically scaling. When you have resources in three AZs using the regional NAT Gateway, <a href="https://aws.amazon.com/vpc/pricing/">you’re charged for three AZs</a>.</p>

<p>The clever bit is what happens when your workloads change. Say you’re running a scheduled job that only uses two AZs during off-peak hours. So far you would be still paying for all three NAT Gateways. Regional NAT Gateway does adjust automatically. When no traffic flows through an AZ, you stop paying for that AZ. When traffic resumes, pricing scales back up.</p>

<p>So you’re not saving money if you’re running steady workloads across multiple AZs. You’re getting operational simplicity - one resource to manage instead of three - but you’re paying the same hourly charges. The cost benefit comes if your workloads are dynamic, expanding and contracting across AZs throughout the day.</p>

<p>There is also another way Regional NAT Gateway can save you money (and improve your resilience to AZ failures) - it prevents cross-AZ data transfers from misconfiguration. With traditional NAT Gateways, if you accidentally made route table in AZ-A to point to a NAT Gateway in AZ-B, you were paying cross-AZ data transfer charges on top of everything else.</p>

<p>Think of it this way - you’re trading the complexity of managing multiple NAT Gateways for the flexibility of automatic AZ scaling. The price stays the same for equivalent usage, but you’re getting operational simplicity and protection from costly misconfigurations.</p>

<h2 id="small-print">Small Print</h2>

<h4 id="scaling-out">Scaling Out</h4>
<p>Regional NAT Gateway can take up to <a href="https://docs.aws.amazon.com/vpc/latest/userguide/nat-gateways-regional.html">60 minutes to expand to new AZs</a>. This isn’t at speed of EC2 Auto Scaling launching instances in 2-3 minutes or functions scaling in seconds, but it shouldn’t be a major issue because</p>

<blockquote>
  <p><em>Until this expansion is complete, the relevant traffic from this resource is processed across zones by your regional NAT Gateway in one of the existing Availability Zones</em>.</p>
</blockquote>

<h4 id="pricing">Pricing</h4>
<p><a href="https://aws.amazon.com/vpc/pricing/">Regional NAT Gateway charges</a> per AZ, but how is it detected if an AZ is “in use”? The <a href="https://docs.aws.amazon.com/vpc/latest/userguide/nat-gateways-regional.html">documentation</a> is bit vague but it seems to be based on presence of an elastic network interface (ENI) rather than traffic detection.</p>

<blockquote>
  <p><em>regional NAT gateway detects the presence of an network interface(ENI) in that Availability Zone and automatically expands to that zone. Similarly, the NAT Gateway contracts from the Availability Zone that has no active workloads.</em></p>
</blockquote>

<p>Expansion to new AZ is said to typically take 15-20 minutes but can take up to 60 min. Documentation doesn’t say, but I would expect scale in from unused AZs to follow similar process. And if you stop your instance but ENI remains, I would expect that AZ remain “in use” from NAT point-of-view.</p>

<h4 id="public-nat-only">Public NAT Only</h4>
<p>At launch regional NAT gateway does not support private NAT. For <a href="https://docs.aws.amazon.com/whitepapers/latest/building-scalable-secure-multi-vpc-network-infrastructure/private-nat-gateway.html">private NAT gateways</a> you should continue to use classic zonal NAT gateways.</p>

<h2 id="summary">Summary</h2>

<p>Regional NAT Gateway is what NAT Gateway should have been from the start.</p>

<p><strong>Architectural &amp; Operational simplicity</strong> - <a href="https://docs.aws.amazon.com/vpc/latest/userguide/nat-gateways-regional.html">One NAT Gateway per VPC</a> instead of one per AZ. No more managing multiple resources, no more AZ-specific route tables to keep synchronized. When workloads expand to new AZs, Regional NAT Gateway handles it automatically. For purely outbound architectures, you can eliminate public subnets entirely. Simpler network topology, fewer components to secure and maintain.</p>

<p><strong>Protection from mistakes</strong> - No risk of misconfigured route tables causing cross-AZ data transfer charges. Traffic automatically routes through the NAT Gateway capacity in the same AZ as your resources.</p>

<p><strong>Better capacity</strong> - Up to <a href="https://docs.aws.amazon.com/vpc/latest/userguide/nat-gateways-regional.html">32 IP addresses per AZ</a> compared to 8 for classic NAT Gateway. Automatic IP scaling when connections approach limits. Better suited for <a href="/aws/vpc/nat/tgw/cost/saving/2022/02/07/sharing-natgw.html">shared NAT scenarios</a> and high-connection workloads.</p>

<p><strong>Cost efficiency for dynamic workloads</strong> - <a href="https://aws.amazon.com/vpc/pricing/">Only pay for AZs</a> in-use. If your workloads scale across AZs throughout the day, you stop paying for idle NAT capacity.</p>

<p><strong>Advanced routing options</strong> - <a href="https://aws.amazon.com/blogs/networking-and-content-delivery/introducing-amazon-vpc-regional-nat-gateway/">NAT gateway route table</a> enables traffic inspection through middleboxes like firewalls, something that required complex routing workarounds with classic NAT Gateway.</p>

<p>The pricing is the same for equivalent usage, so you’re not paying extra for these benefits. You’re getting operational simplicity, architectural flexibility, and protection from common misconfigurations at no additional cost.</p>

<p>There’s no compelling reason to deploy new classic NAT Gateways. Regional NAT Gateway is available in all commercial AWS regions. If you’re designing new VPCs or refactoring existing ones, make your NAT regional. And if you’re running classic NAT Gateways in production, start <a href="https://docs.aws.amazon.com/vpc/latest/userguide/nat-gateways-regional.html">planning the migration</a>. The architecture is simpler, the operations are easier, and you’re eliminating entire classes of configuration mistakes that cost money and cause outages.</p>]]></content><author><name>kallu</name></author><category term="aws" /><category term="vpc" /><category term="nat" /><category term="regional" /><summary type="html"><![CDATA[Shortly after I published my post about how "You don’t need NAT gateway to deploy Lambda into VPC", AWS announced Regional NAT Gateway. Whilst IPv6 eliminates the need for NAT entirely, Regional NAT Gateway represents a major update to best practices for IPv4 VPC networking.]]></summary></entry><entry><title type="html">You don’t need NAT gateway to deploy Lambda into VPC</title><link href="https://carriagereturn.nl/aws/lambda/ipv6/vpc/nat/2025/11/16/lambda-ipv6-vpc.html" rel="alternate" type="text/html" title="You don’t need NAT gateway to deploy Lambda into VPC" /><published>2025-11-16T07:00:00+00:00</published><updated>2025-11-16T07:00:00+00:00</updated><id>https://carriagereturn.nl/aws/lambda/ipv6/vpc/nat/2025/11/16/lambda-ipv6-vpc</id><content type="html" xml:base="https://carriagereturn.nl/aws/lambda/ipv6/vpc/nat/2025/11/16/lambda-ipv6-vpc.html"><![CDATA[<p><img src="/img/ipv6-nat/wd.png" hspace="20" align="right" width="40%" />
Remember that <a href="https://www.youtube.com/watch?v=D0JbbRFuMhw">Wheeler Dealers episode</a> where Ant converted a Maserati Biturbo to electric?
Bold move taking a classic V6 (pun intended) and swapping it for batteries and electric motors.
But the result was brilliant - same car, same look, but running cleaner and cheaper with modern technology
under the bonnet.</p>

<p>That’s exactly what we’re doing today with Amazon Web Services (AWS) Lambda functions in Amazon Virtual Private Cloud (VPC).</p>

<h2 id="vpc-dealers---the-electric-conversion">VPC Dealers - The Electric Conversion</h2>

<p>In this episode I’ve got a Lambda function that’s been deployed into a VPC for years. It needs VPC access
to reach private resources like databases or internal APIs. But it also needs to call AWS APIs and maybe
some external services on the Internet. The classic solution? Deploy to VPC private subnets with a route
to Amazon VPC NAT Gateway (NAT) in a public subnet.</p>

<p><a href="/img/ipv6-nat/ipv4.png"><img src="/img/ipv6-nat/ipv4.png" hspace="20" width="90%" /></a></p>

<p>It works. No question about it. But here’s the thing - NAT gateway charges you by the hour, every hour,
whether you’re using it or not. For a Lambda function that might only run a few times a day, you’re paying
for 24/7 infrastructure. It’s like leaving the engine running in the car park all day just in case you need
to pop to the shops.</p>

<p>And before you ask - no, you can’t just deploy Lambda to a public subnet. Lambda functions in VPC <a href="https://docs.aws.amazon.com/lambda/latest/dg/configuration-vpc.html">never
get a public IP address</a>, even when deployed to public subnets. They always need NAT gateway
or some other route to reach the Internet.</p>

<h3 id="classic-solutions">Classic Solutions</h3>

<p>Now, there are traditional ways to reduce NAT gateway costs. You could use VPC endpoints for AWS services
like Amazon Simple Storage Service (S3) and Amazon DynamoDB to bypass the NAT gateway entirely for that traffic. You could consolidate multiple
NAT gateways into one if you’re running several. You could even replace NAT gateway with a NAT instance
on a small Amazon Elastic Compute Cloud instance that you manage yourself.</p>

<p>All valid approaches. But they’re a bit like tuning the old engine - you’re still paying for something
that sits there burning money even when idle. VPC endpoints help but only for specific AWS services.
NAT instances save money but add operational overhead.</p>

<h3 id="why-nat-gateway-exists">Why NAT Gateway Exists</h3>

<p>Let’s step back and understand what NAT gateway actually does. With IPv4, you’ve got a limited pool of
public IP addresses. Your VPC uses private IP addresses internally (10.0.0.0/8, 172.16.0.0/12, 192.168.0.0/16)
that aren’t routable on the Internet. When your Lambda needs to reach the Internet, NAT gateway translates
that private IP to a public IP address, sends the request out, receives the response, and translates it
back to your private IP. It’s Network Address Translation (NAT). The gateway sits in a public subnet with
an Elastic IP, acting as a middleman for all your outbound traffic.</p>

<h3 id="ipv6-changes-everything">IPv6 Changes Everything</h3>

<p>Here’s the thing about IPv6 - there’s no address shortage. IPv6 has 2^128 (that’s 39 digits!)
Every resource in your VPC can have a globally unique, routable IPv6 address. No translation needed.</p>

<p>When your Lambda function has an IPv6 address it can talk directly to the Internet. No middleman. No NAT
gateway sitting there charging you by the hour. You just need an <a href="https://docs.aws.amazon.com/vpc/latest/userguide/egress-only-internet-gateway.html">egress-only internet gateway</a>.
Like a regular Amazon VPC Internet Gateway, it’s a highly available regional service that scales automatically.
It allows outbound IPv6 traffic while blocking inbound connections - keeping your Lambda in private subnet
just as secure as it was behind the traditional NAT gateway.</p>

<h3 id="electric-conversion">Electric Conversion</h3>

<p>So what does this conversion actually look like? I’ve put together a <a href="https://github.com/kallu/aws-templates/blob/master/misc/lambda-in-vpc-without-natgw.yaml">AWS CloudFormation template</a>
that shows the key changes. Let’s walk through what’s different from a traditional IPv4 VPC setup.</p>

<p>First, I need to associate an IPv6 CIDR block with the VPC. AWS provides these for free, no need to worry
about paying for public IPs like with IPv4.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">IPv6CidrBlock</span><span class="pi">:</span>
  <span class="na">Type</span><span class="pi">:</span> <span class="s">AWS::EC2::VPCCidrBlock</span>
  <span class="na">Properties</span><span class="pi">:</span>
    <span class="na">VpcId</span><span class="pi">:</span> <span class="kt">!Ref</span> <span class="s">VPC</span>
    <span class="na">AmazonProvidedIpv6CidrBlock</span><span class="pi">:</span> <span class="kc">true</span>
</code></pre></div></div>

<p>Then subnets need IPv6 CIDR blocks. Notice <code class="language-plaintext highlighter-rouge">AssignIpv6AddressOnCreation</code> - this ensures Lambda
ENIs get IPv6 addresses automatically.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">PrivateSubnet1</span><span class="pi">:</span>
  <span class="na">Type</span><span class="pi">:</span> <span class="s">AWS::EC2::Subnet</span>
  <span class="na">DependsOn</span><span class="pi">:</span> <span class="s">IPv6CidrBlock</span>
  <span class="na">Properties</span><span class="pi">:</span>
    <span class="na">VpcId</span><span class="pi">:</span> <span class="kt">!Ref</span> <span class="s">VPC</span>
    <span class="na">CidrBlock</span><span class="pi">:</span> <span class="s">10.0.0.0/25</span>
    <span class="na">Ipv6CidrBlock</span><span class="pi">:</span> <span class="kt">!Select</span> <span class="pi">[</span><span class="nv">0</span><span class="pi">,</span> <span class="kt">!Cidr</span> <span class="pi">[</span><span class="kt">!Select</span> <span class="pi">[</span><span class="nv">0</span><span class="pi">,</span> <span class="kt">!GetAtt</span> <span class="nv">VPC.Ipv6CidrBlocks</span><span class="pi">],</span> <span class="nv">2</span><span class="pi">,</span> <span class="nv">64</span><span class="pi">]]</span>
    <span class="na">AvailabilityZone</span><span class="pi">:</span> <span class="kt">!Select</span> <span class="pi">[</span><span class="nv">0</span><span class="pi">,</span> <span class="kt">!GetAZs</span> <span class="s1">'</span><span class="s">'</span><span class="pi">]</span>
    <span class="na">AssignIpv6AddressOnCreation</span><span class="pi">:</span> <span class="kc">true</span>
</code></pre></div></div>

<p>Instead of a NAT gateway, I create an Amazon VPC Egress-Only Internet Gateway. This is attached to VPC
like Internet gateway. No public subnets required.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">EgressOnlyInternetGateway</span><span class="pi">:</span>
  <span class="na">Type</span><span class="pi">:</span> <span class="s">AWS::EC2::EgressOnlyInternetGateway</span>
  <span class="na">Properties</span><span class="pi">:</span>
    <span class="na">VpcId</span><span class="pi">:</span> <span class="kt">!Ref</span> <span class="s">VPC</span>
</code></pre></div></div>

<p>Route table points IPv6 traffic (<code class="language-plaintext highlighter-rouge">::/0</code>) to the Egress-only gateway instead of a NAT gateway.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">PrivateRouteIPv6</span><span class="pi">:</span>
  <span class="na">Type</span><span class="pi">:</span> <span class="s">AWS::EC2::Route</span>
  <span class="na">Properties</span><span class="pi">:</span>
    <span class="na">RouteTableId</span><span class="pi">:</span> <span class="kt">!Ref</span> <span class="s">PrivateRouteTable</span>
    <span class="na">DestinationIpv6CidrBlock</span><span class="pi">:</span> <span class="s">::/0</span>
    <span class="na">EgressOnlyInternetGatewayId</span><span class="pi">:</span> <span class="kt">!Ref</span> <span class="s">EgressOnlyInternetGateway</span>
</code></pre></div></div>

<p>Security groups need to allow IPv6 egress traffic.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">LambdaSecurityGroup</span><span class="pi">:</span>
  <span class="na">Type</span><span class="pi">:</span> <span class="s">AWS::EC2::SecurityGroup</span>
  <span class="na">Properties</span><span class="pi">:</span>
    <span class="na">GroupDescription</span><span class="pi">:</span> <span class="s">Security group for Lambda function</span>
    <span class="na">VpcId</span><span class="pi">:</span> <span class="kt">!Ref</span> <span class="s">VPC</span>
    <span class="na">SecurityGroupEgress</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">IpProtocol</span><span class="pi">:</span> <span class="s">-1</span>
        <span class="na">CidrIp</span><span class="pi">:</span> <span class="s">0.0.0.0/0</span>
      <span class="pi">-</span> <span class="na">IpProtocol</span><span class="pi">:</span> <span class="s">-1</span>
        <span class="na">CidrIpv6</span><span class="pi">:</span> <span class="s">::/0</span>
</code></pre></div></div>

<p>And finally, the Lambda function needs one crucial setting - <code class="language-plaintext highlighter-rouge">Ipv6AllowedForDualStack: true</code>.
This tells Lambda to <a href="https://aws.amazon.com/about-aws/whats-new/2023/10/aws-lambda-ipv6-outbound-connections-vpc/">use IPv6 for outbound connections</a>:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">MyLambdaFunction</span><span class="pi">:</span>
  <span class="na">Type</span><span class="pi">:</span> <span class="s">AWS::Serverless::Function</span>
  <span class="na">Properties</span><span class="pi">:</span>
    <span class="na">VpcConfig</span><span class="pi">:</span>
      <span class="na">SubnetIds</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="kt">!Ref</span> <span class="s">PrivateSubnet1</span>
        <span class="pi">-</span> <span class="kt">!Ref</span> <span class="s">PrivateSubnet2</span>
      <span class="na">SecurityGroupIds</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="kt">!Ref</span> <span class="s">LambdaSecurityGroup</span>
      <span class="na">Ipv6AllowedForDualStack</span><span class="pi">:</span> <span class="kc">true</span>
</code></pre></div></div>

<p>That’s it. No public subnets. No NAT gateway. No Elastic IPs. Just private subnets with IPv6 and an
Egress-only gateway. Same functionality, zero ongoing infrastructure costs.</p>

<p><a href="/img/ipv6-nat/ipv6.png"><img src="/img/ipv6-nat/ipv6.png" hspace="20" width="90%" /></a></p>

<h3 id="other-considerations">Other Considerations</h3>

<p>Almost all <a href="https://docs.aws.amazon.com/vpc/latest/userguide/aws-ipv6-support.html">AWS services support IPv6</a> these days. Your Lambda can talk to S3, DynamoDB,
Amazon API Gateway, Amazon Simple Queue Service (SQS), Amazon Simple Notification Service (SNS) - all over IPv6. No issues there. And surprisingly, many Internet services also
speak IPv6. Major CDNs, cloud providers, and APIs have had IPv6 support for years.</p>

<p>And if you’re exposing your own services to IPv4 clients through an Application Load Balancer or Amazon CloudFront, dual-stack mode
lets the load balancer handle IPv4 clients connecting to your IPv6 backend.</p>

<p>Your VPC resources can still use their private IPv4 addresses for internal communication. This is dual-stack
mode - both IPv4 and IPv6 work simultaneously. Your Lambda talks to Amazon Relational Database Service (RDS) using the same private IPv4 address
it always has. Only outbound Internet traffic uses IPv6. This makes the conversion backward compatible and
low risk.</p>

<p>Now, what about services that only speak IPv4? AWS offers <a href="https://docs.aws.amazon.com/vpc/latest/userguide/nat-gateway-nat64-dns64.html">NAT64 and DNS64</a> services that translate
between IPv6 and IPv4. But here’s the catch - NAT64 gateway has the similar hourly charges as a regular NAT
gateway. You’re back to paying for infrastructure. If you need to reach IPv4-only services, you might be
better off keeping a traditional NAT gateway.</p>

<p>The sweet spot for this approach is Lambda functions that primarily call AWS services and APIs that
support IPv6. For those workloads, you can eliminate NAT gateway costs entirely while keeping everything
else exactly as it was.</p>

<h2 id="summary">Summary</h2>

<p>In this episode of VPC Dealers we took a Lambda function running in a traditional VPC with NAT gateway and
converted it to use IPv6 with an egress-only Internet gateway. Same functionality, same security posture,
but without the hourly infrastructure charges. Just like Ant’s electric Maserati - modern technology under
the same classic bonnet.</p>

<p>If you’ve got Lambda functions in VPCs that are costing you money in NAT gateway charges, give this approach
a try. The <a href="https://github.com/kallu/aws-templates/blob/master/misc/lambda-in-vpc-without-natgw.yaml">template is on GitHub</a> ready to deploy.</p>

<p>Until next time. Ta-Da!</p>]]></content><author><name>kallu</name></author><category term="aws" /><category term="lambda" /><category term="ipv6" /><category term="vpc" /><category term="nat" /><summary type="html"><![CDATA[In this episode of VPC Dealers we're taking on a Lambda function that's been running in a VPC with NAT gateway for years. It works fine but those hourly charges keep adding up. Time to do what Ant did with that Maserati Biturbo - rip out the old combustion engine and drop in something electric. We're converting from NAT gateway to Egress-only gateway with IPv6, cutting the running costs while keeping all the functionality.]]></summary></entry><entry><title type="html">Debugging Lambda</title><link href="https://carriagereturn.nl/aws/lambda/debug/2025/07/25/lambda-debugging.html" rel="alternate" type="text/html" title="Debugging Lambda" /><published>2025-07-25T10:00:00+00:00</published><updated>2025-07-25T10:00:00+00:00</updated><id>https://carriagereturn.nl/aws/lambda/debug/2025/07/25/lambda-debugging</id><content type="html" xml:base="https://carriagereturn.nl/aws/lambda/debug/2025/07/25/lambda-debugging.html"><![CDATA[<p>Nowadays you should always ask your friendly LLM first. So I did.</p>

<blockquote>
  <p>What is the best way to debug AWS Lambda functions?</p>
</blockquote>

<p>Answer was a long list of advice including test events, logging, <a href="https://docs.aws.amazon.com/xray/latest/devguide/aws-xray.html">AWS X-Ray</a>, and running
functions locally on your laptop using <a href="https://docs.aws.amazon.com/serverless-application-model/latest/developerguide/using-sam-cli-local.html"><code class="language-plaintext highlighter-rouge">sam local</code></a> or <a href="https://www.localstack.cloud/">LocalStack</a>. 
While all great advice, all of those require rather complex setup and don’t really let you debug
code in its native environment (to avoid works-on-my-machine -syndrome). While setup could be
justified for full-time dev(ops), it isn’t really feasible when you are on-duty and suddenly pulled
into debugging a function that you have never seen before.</p>

<p>Fortunately there is a way to debug ad-hoc lambda functions running in their native environment, with minimal setup.</p>

<h3 id="lambda-remote-debugging">Lambda Remote Debugging</h3>

<p>This is the <a href="https://aws.amazon.com/blogs/aws/simplify-serverless-development-with-console-to-ide-and-remote-debugging-for-aws-lambda/">new feature</a> my chatbot wasn’t aware of (yet)</p>

<blockquote>
  <p>AWS Lambda now supports remote debugging in Visual Studio Code (VS Code), enabling developers to debug their Lambda functions running in the cloud directly from their local IDE. With this new capability, developers can use familiar debugging tools like breakpoints, variable inspection, and step-through debugging with functions deployed in the cloud without modifying their existing development workflow, thus accelerating their serverless development process.</p>
</blockquote>

<p>Wow! Also the list of pre-requirements for remote debugging doesn’t look too bad for casual debugger,
especially when compared to any of above options.</p>

<ul>
  <li><a href="https://code.visualstudio.com/">VS Code</a></li>
  <li><a href="https://aws.amazon.com/visualstudiocode/">AWS Toolkit</a></li>
  <li>AWS Credentials</li>
</ul>

<h3 id="getting-started">Getting started</h3>

<p>To get started you just browse to AWS Lambda Console, find your function and click.</p>

<p><a href="/img/lambda-debugging/lambda-console.png"><img src="/img/lambda-debugging/lambda-console.png" hspace="20" width="90%" /></a>
<a href="/img/lambda-debugging/add-region.png"><img src="/img/lambda-debugging/add-region.png" align="right" hspace="20" width="50%" /></a></p>

<p>This will open the function in your VS Code and if you don’t have recent version of AWS Toolkit, it will
take care of that too. For now AWS Console can only open VS Code, but actually any VS Code derivative
like <a href="https://kiro.dev/">Kiro</a> will work. Important part is AWS Toolkit. You can also open debugging session from your
editor and select the function from AWS Toolkit Explorer. By default you will see only the default region
configured for your credentials. If you don’t see the function you were looking for, verify you have
enabled the correct region.</p>

<p>I’d also recommend you to spend 5 minutes and watch <a href="https://www.linkedin.com/in/singledigit/">Eric Johnson’s</a> demo below.</p>

<p><a href="https://www.youtube.com/watch?v=gYoUifln-Z8" target="_blank"><img src="/img/lambda-debugging/youtube.png" hspace="20" width="80%" /></a></p>

<h3 id="debug-this">Debug this</h3>

<p>Sometimes seeing is believing, but nothing beats getting hands-on. For this I created a template that
creates a sample python function with a bug. You can get the template from <a href="https://github.com/kallu/aws-lambda-debug">github -repo</a>
and deploy it with AWS CLI or from AWS CloudFormation console. Code and minimal infrastructure are both
included in single file for easy deployment.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>% aws cloudformation deploy <span class="nt">--template-file</span> template-bug.yaml <span class="nt">--stack-name</span> lambda-debug-demo <span class="nt">--capabilities</span> CAPABILITY_AUTO_EXPAND CAPABILITY_IAM CAPABILITY_NAMED_IAM
</code></pre></div></div>

<p>And then get the function URL from stack outputs using AWS CLI or from AWS CloudFormation console</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>% aws cloudformation describe-stacks <span class="nt">--stack-name</span> lambda-debug-demo <span class="nt">--query</span> <span class="s1">'Stacks[0].Outputs[].[Description,OutputValue]'</span>
<span class="o">[</span>
    <span class="o">[</span>
        <span class="s2">"Lambda Function URL"</span>,
        <span class="s2">"https://LAMBDA-FUNCTION-URL.lambda-url.eu-west-1.on.aws/"</span>
    <span class="o">]</span>,
    <span class="o">[</span>
        <span class="s2">"Hello World Lambda Function ARN"</span>,
        <span class="s2">"arn:aws:lambda:eu-west-1:123456789012:function:lambda-debug-HelloWorldFunction-OI7DQCVooNx7"</span>
    <span class="o">]</span>
<span class="o">]</span>
</code></pre></div></div>

<p>If you now call plain function URL <code class="language-plaintext highlighter-rouge">https://LAMBDA-FUNCTION-URL.lambda-url.eu-west-1.on.aws/</code> or with URL parameter <code class="language-plaintext highlighter-rouge">user_id=foo</code> you can see how the value from from <code class="language-plaintext highlighter-rouge">process_user_data()</code> keep growing after each call.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Lambda Function Debug Info
=============================

BUG DEMONSTRATION - Mutable Default Argument:
Notice how the list keeps growing between calls!
process_user_data() returns: 
[{'timestamp': '2025-07-25T18:27:55.517622',
  'user_id': 'anonymous'},
 {'timestamp': '2025-07-25T18:28:06.864674',
  'user_id': 'anonymous'},
 {'timestamp': '2025-07-25T18:28:21.197582',
  'user_id': 'foo'}]
</code></pre></div></div>

<p>But looking at the code, it should only return info about current call</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code>    <span class="k">def</span> <span class="nf">process_user_data</span><span class="p">(</span><span class="n">user_id</span><span class="p">,</span> <span class="n">metadata</span><span class="o">=</span><span class="p">[]):</span>
        <span class="c1"># BUG: Mutable default argument - list persists between calls!
</span>        <span class="n">metadata</span><span class="p">.</span><span class="nf">append</span><span class="p">({</span>
            <span class="sh">'</span><span class="s">timestamp</span><span class="sh">'</span><span class="p">:</span> <span class="n">datetime</span><span class="p">.</span><span class="nf">now</span><span class="p">().</span><span class="nf">isoformat</span><span class="p">(),</span>
            <span class="sh">'</span><span class="s">user_id</span><span class="sh">'</span><span class="p">:</span> <span class="n">user_id</span>
        <span class="p">})</span>
        <span class="k">return</span> <span class="n">metadata</span>
</code></pre></div></div>

<p>I will leave fixing this for reader to test debugging and your favorite LLM. Or you can check <a href="https://github.com/kallu/aws-lambda-debug/blob/main/debug.md">debug.md</a>.</p>

<h3 id="things-to-consider">Things to consider</h3>

<p>While remote debugging of Lambda functions is a great feature it doesn’t come without some limitations.
1) At the moment it works with recent Python, Node.js and Java functions. 2) Debugging attach an extra
layer to function. This will add about 40MB on top of functon total size that must remain within limit
of 250MB. 3) Connection from remote function to AWS Toolkit running in local IDE is established using
IoT tunnel. If you have strict least privilege IAM policies, it might be necessary to add permission
for <code class="language-plaintext highlighter-rouge">iot:OpenTunnel</code> for credentials you use in AWS Toolkit.</p>

<p>And finally, eventhough Lambda remote debugging is marketed as developer feature, I think it also has
a lot of value for the Ops in devops as it allows ad-hoc debugging with minimal pre-requirements.</p>]]></content><author><name>kallu</name></author><category term="aws" /><category term="lambda" /><category term="debug" /><summary type="html"><![CDATA[AWS Lambda remote debugging allows debugging Lambda functions running in the cloud directly from local IDE. With this new capability, it is possible use familiar debugging tools like breakpoints, variable inspection, and step-through debugging with functions deployed in the cloud.]]></summary></entry><entry><title type="html">Analyze This</title><link href="https://carriagereturn.nl/aws/vpc/network/reachability/analyzer/2025/06/19/analyzethis.html" rel="alternate" type="text/html" title="Analyze This" /><published>2025-06-19T10:00:00+00:00</published><updated>2025-06-19T10:00:00+00:00</updated><id>https://carriagereturn.nl/aws/vpc/network/reachability/analyzer/2025/06/19/analyzethis</id><content type="html" xml:base="https://carriagereturn.nl/aws/vpc/network/reachability/analyzer/2025/06/19/analyzethis.html"><![CDATA[<p>I’ll continue with network topics with the new episode of VPC Dealers ;-)</p>

<p>If you missed the first episode you can find it <a href="/aws/vpc/origin/network/redesign/2024/12/30/vpc-dealers.html">here</a>.</p>

<h3 id="to-improve-your-mean-time-to-innocence-mtti">To improve your mean time to innocence (MTTI)</h3>

<p>Those of you who have been working as network admin or someone who’s work depends on network, you know when things stop working, network is always first to blame until proven innocent. Legal principle of one <a href="https://en.wikipedia.org/wiki/Presumption_of_innocence">presumed innocence</a> until prove guilty just doesn’t apply here.
To get to correct root cause it is important to quickly rule out, or find evidence of, network problems. This is where <a href="https://docs.aws.amazon.com/vpc/latest/reachability/what-is-reachability-analyzer.html">AWS Reachability Analyzer</a> can help network admins but also let anyone to verify basic requirements for connectivity from point A to B (and back again) are in-place.</p>

<h3 id="what-is-aws-reachability-analyzer">What is AWS Reachability Analyzer?</h3>

<p><a href="https://docs.aws.amazon.com/vpc/latest/reachability/what-is-reachability-analyzer.html">AWS Reachability Analyzer</a> is a network diagnostic service that helps to analyze and troubleshoot network connectivity within your VPC environment. It is designed to verify whether there is path between 2 points in network and identify potential connectivity blockers on the path. Hop-by-hop analysis and pointing out configuration issues can help also non-network specialist to fix connectivity issues. It isn’t actually a new service but has been around <a href="https://aws.amazon.com/blogs/aws/new-vpc-insights-analyzes-reachability-and-visibility-in-vpcs/">since Dec 2020</a>.</p>

<p>Since then it has got more features such as ability to <a href="https://aws.amazon.com/blogs/networking-and-content-delivery/visualize-and-diagnose-network-reachability-across-aws-accounts-using-reachability-analyzer/">analyze path across multiple VPC connected via AWS Transit Gateway</a> and most recently <a href="https://aws.amazon.com/about-aws/whats-new/2025/05/amazon-vpc-reachability-analyzer-resource-exclusion/">ability exclude resources</a> that should not part of the path. The later got me interested
again to take another look what it would be capable of.</p>

<p>Analysis is performed by looking at the configuration of AWS network resources. Reachability Analyzer doesn’t sent any packets. This makes it safe to use in any environment but can also limit it’s ability test paths traveling through some networks. See “Small print” -chapter later in this post.</p>

<p><a href="/img/analyze-this/deploy.png"><img src="/img/analyze-this/deploy.png" align="right" hspace="20" width="40%" /></a></p>
<h3 id="is-there-a-path-from-a-to-b">Is there a path from A to B?</h3>

<p>To demonstrate how Reachability Analyzer works I wrote a <a href="https://github.com/kallu/aws-reachability-analyser">template you can use to create VPC similar to below diagram</a>.
It shows just a single availability zone but you can extend it using <code class="language-plaintext highlighter-rouge">AvailabilityZones</code> parameter and list extra AZs as lower-case letters separated by commas. For initial deployment you shoud leave <code class="language-plaintext highlighter-rouge">BrokenNACL</code> to false. We will get back to that later.</p>

<p>Template will not create any EC2 instances but use ENIs as source or target in network analysed paths. From analysis point of this is the same as EC2 instances and other resources are seen as one or multiple network interface in VPC. ENIs itself are free of charge but you would pay for public IPs and analysis.</p>

<p><a href="/img/analyze-this/setup.png"><img src="/img/analyze-this/setup.png" hspace="20" width="80%" /></a></p>

<p>Template also creates 3 paths you can test and see how the analysis works.</p>

<ul>
  <li>Path from Public ENI to Private ENI.</li>
  <li>Path from Private ENI to Internet (8.8.8.8).</li>
  <li>Path from Public ENI to Internet (8.8.8.8).</li>
</ul>

<p>If you deploy the template for multiple AZs then there is going to be a similar set of 3 paths created for each AZ.
You will find Reachability Analyzer in AWS Network Manager in AWS console. There you can select one of the paths and click Analyze path from Actions -menu as shown below.</p>

<p><a href="/img/analyze-this/analyze.png"><img src="/img/analyze-this/analyze.png" hspace="20" width="80%" /></a></p>

<p>Let’s analyze first the path from private subnet to Internet. Here is how the results look like. Besides just telling you this path works it is worth while reading through as it also shows you step-by-step what are all things you need to have to make that happen. Or if there is a misconfiguration in any of those it would block the access. And when you expand “Outbound header” you see how the packet source address changes when it goes out from Internet Gateway, not at the NAT gateway as you might first think.</p>

<p><a href="/img/analyze-this/path-priv2inet.png"><img src="/img/analyze-this/path-priv2inet.png" hspace="20" width="80%" /></a></p>

<p>Let’s try next path from public subnet to Internet. This should be more simple as there is no NAT gateway in the path but route is directly from ENI to Internet Gateway. If you look how public subnets are configured, you can see there is <code class="language-plaintext highlighter-rouge">MapPublicIpOnLaunch: true</code>. This does assign a public IP for things launched to subnet and you would expect the route from instance to Internet work. Right?</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Type: AWS::EC2::Subnet
    Properties:
        VpcId: !Ref VPC
        AvailabilityZone: !Sub ${AWS::Region}${X}
        MapPublicIpOnLaunch: true       
</code></pre></div></div>

<p><a href="/img/analyze-this/path-pub2inet.png"><img src="/img/analyze-this/path-pub2inet.png" hspace="20" width="80%" /></a></p>

<p>But it fails and says there is no public IP associated for egress ?!? To understand what happened
here you would have to read the VPC documentation rather carefully, especially <a href="https://docs.aws.amazon.com/vpc/latest/userguide/vpc-ip-addressing.html#vpc-public-ipv4-addresses">the part</a> that says</p>

<blockquote>
  <p>Therefore, when you launch an instance into a subnet that has this attribute enabled, a public IP address is assigned to the primary network interface that’s created for the instance. A public IP address is mapped to the primary private IP address through network address translation (NAT).</p>
</blockquote>

<p>But since we created just stand-a-lone ENIs, these are not considered as primary interfaces and thereforee
don’t get a public IPs. The NAT above text refers is not your NAT Gateway but Internet Gateway that is
a NAT device too. I will leave fixing this as an excersice for the reader ;-)</p>

<p>Now you can run analysis for the last remaining path from private ENI to public ENI to verify you VPC routing
and security groups are properly configured. Once you have verified this path is working, go back to Cloudformation
console and change this parameter from false to true to add misconfigured NACL to VPC.</p>

<p><a href="/img/analyze-this/brokenNACL.png"><img src="/img/analyze-this/brokenNACL.png" hspace="20" width="80%" /></a></p>

<p>Then re-run analysis for private to public path to see how analysis finds a common mis-configuration where
NACL allows only one-way traffic, and because it is stateless, return packets are not automatically allowed
as it would be for security groups.</p>

<h3 id="advanced-use-cases">Advanced use-cases</h3>

<p>Since the introduction Reachability Analyzer has gained many new skills. It can analyze paths
through Transit Gateway and multiple AWS accounts as shown in <a href="https://aws.amazon.com/blogs/networking-and-content-delivery/visualize-and-diagnose-network-reachability-across-aws-accounts-using-reachability-analyzer/">this demo</a>. Another feature
that caught my eye was <a href="https://aws.amazon.com/about-aws/whats-new/2025/05/amazon-vpc-reachability-analyzer-resource-exclusion/">ability to exclude components</a> that can be in the path.
Being able to say certain component can not be part of the path lets you to find paths that
you didn’t want to have, but were accidentially created due to misconfiguration.</p>

<p>In my simple setup one such case could be testing path from private ENI to Internet with exclusion
of NAT Gateway in the same AZ. If this analysis fails, you know your routing is correctly configured.
If it succeeds, e.g. because you added route from private subnet to internet gateway (and attached
public IP to private ENI) or it goes via NAT gateway in another AZ, you know there is something
wrong. With this feature you can now not only test if you have a connectivity between A and B,
but also test various compliancy scenarios where you want traffic being blocked.</p>

<p>So it is good to remember not all analysis that have failed mean there is something broken.</p>

<h3 id="small-print">Small print</h3>

<p>Reachability Analyzer supports most of common AWS network resources, but not all.
You can find the list of supported resources and scenarios from <a href="https://docs.aws.amazon.com/vpc/latest/reachability/how-reachability-analyzer-works.html">documentation</a>.</p>

<p>Service is priced per analysis run ($0.10/analysis). If this is cheap or expensive depends
on your viewpoint. If you think this can save couple of hours debugging time when your
production systems are down, it is very cheap. But if you run continous analysis of
complex multi-vpc network it can be very expesive solution to feed data to network
operations center dashboard showing everything is working.</p>

<p>And if you are using <a href="https://aws.amazon.com/q/developer/features/#topic-5">Amazon Q Developer</a> to help you connectivity issues, it is actually
using Reachability Analyzer behind the scenes.</p>

<h3 id="summary">Summary</h3>

<p><a href="https://docs.aws.amazon.com/vpc/latest/reachability/what-is-reachability-analyzer.html">AWS Reachability Analyzer</a> does a good job in analyzing network paths. It all happens by
analyzing configuration and not sending any packets. This can be a good thing, separating
network from application level issues, but one should understand it doesn’t actually test if
your service is functioning.</p>

<p>Pre-configured paths can help non-network specialists to check most common paths to either
rule out or get insight what might be the problem in network very quickly, without support
from network team. Another tool to keep in mind is <a href="https://aws.amazon.com/q/developer/features/#topic-5">Q Developer</a> that can be more human
friendly interface for debugging network issues, using Reachability Analyzer.</p>]]></content><author><name>kallu</name></author><category term="aws" /><category term="vpc" /><category term="network" /><category term="reachability" /><category term="analyzer" /><summary type="html"><![CDATA[Those of you who have been working as network admin or someone who's work depends on network, you know when things stop working, network is always first to blame until proven innocent. To get to correct root cause it is important to quickly rule out, or find evidence of, network problems. This is where AWS Reachability Analyzer can help network admins but also let anyone to verify basic requirements for connectivity from point A to B (and back again) are in-place.]]></summary></entry><entry><title type="html">VPC Dealers</title><link href="https://carriagereturn.nl/aws/vpc/origin/network/redesign/2024/12/30/vpc-dealers.html" rel="alternate" type="text/html" title="VPC Dealers" /><published>2024-12-30T13:00:00+00:00</published><updated>2024-12-30T13:00:00+00:00</updated><id>https://carriagereturn.nl/aws/vpc/origin/network/redesign/2024/12/30/vpc-dealers</id><content type="html" xml:base="https://carriagereturn.nl/aws/vpc/origin/network/redesign/2024/12/30/vpc-dealers.html"><![CDATA[<p><img src="/img/vpc-dealers/wheeler-dealers.jpg" hspace="20" align="right" width="40%" />
<a href="https://en.wikipedia.org/wiki/Wheeler_Dealers">“Wheeler Dealers”</a> is a British television series where 2 middle-aged men are restoring cars.
Every episode follows the same plot where they first buy a cheap classic car in need of repair.
Then bring it to the workshop and demonstrate repair techniques, showcasing the work involved in 
bringing the car back to sellable condition. And then list the car for sale, detailing the repairs
and improvements made.</p>

<p>But lets face it, format is getting aged and fixing cars is a bit niche topic these days.
So here is my proposal for the face-lift and synopsis for the pilot episode of …</p>

<h2 id="vpc-dealers">VPC Dealers</h2>

<p>In this episode I’ve inherited an old web service build on common VPC design for its time.
Architecture is basicly ok and fit for the purpose. Public and private resources are in their
separate subnets. Only the application load balancer (ALB) is exposed to internet and EC2
instances in private subnets are protected from direct internet access. But today we
could do better and with little effort, make it run <em>better</em>, <em>cheaper</em> and be <em>more secure</em>. Pick any 3 ;-)</p>

<p><a href="/img/vpc-dealers/old.png"><img src="/img/vpc-dealers/old.png" hspace="20" width="80%" /></a></p>

<h3 id="more-secure">More Secure</h3>

<p>Security is job zero, so lets start from there. If you could remove public subnets and not to expose
any part of your VPC to internet, it would mitigate the possibility of misconfiguration exposing server
or database to internet. As current configuration is using NAT gateways in public subnets as a route to
internet you would have to have an alternative route before decommisioning NAT gateways and being able
to remove public subnets. Luckily the centralised egress is easy to setup with Transit Gateway. If you
don’t already have that in your organisation here is how you can <a href="https://aws.amazon.com/blogs/networking-and-content-delivery/creating-a-single-internet-exit-point-from-multiple-vpcs-using-aws-transit-gateway/">configure a shared route to internet</a>
for all your VPCs. And it comes with <a href="https://aws.amazon.com/blogs/networking-and-content-delivery/building-an-egress-vpc-with-aws-transit-gateway-and-the-aws-cdk/">CDK build</a> too.</p>

<p>Great thing about central egress VPC is it doesn’t affect your developer experience and it gives you a perfect
locatation to add egress filtering later as additional layer of security.
See <a href="https://docs.aws.amazon.com/prescriptive-guidance/latest/transitioning-to-multiple-aws-accounts/centralized-egress.html">Centralized egress</a> in AWS Prescriptive Guidance for best practices of securing egress traffic.</p>

<h3 id="cheaper">Cheaper</h3>

<p>As we managed to <a href="/aws/vpc/nat/tgw/cost/saving/2022/02/07/sharing-natgw.html">replace multiple NAT gateways with TGW attachment it will be cheaper to run</a>.
This is especially important when you have 10’s or 100’s VPCs but every VPC counts. At the same time we
also removed 2 public elastic IPs (for NAT gateways) and 2 or more public IPs for ALB. As you might remember
<a href="https://aws.amazon.com/blogs/aws/new-aws-public-ipv4-address-charge-public-ip-insights/">all public IPv4 addresses cost you</a>. Removing those will keep your FinOps -team happy.</p>

<p><a href="/img/vpc-dealers/changes.png"><img src="/img/vpc-dealers/changes.png" hspace="20" width="80%" /></a></p>

<h3 id="better">Better</h3>

<p>But what happened to public ALB and why I didn’t delete the internet gateway with public subnets?</p>

<p>In November 2024 a new feature <a href="https://aws.amazon.com/blogs/networking-and-content-delivery/introducing-cloudfront-virtual-private-cloud-vpc-origins-shield-your-web-applications-from-public-internet/">Cloudfront VPC Origins</a> was announced. This is was such a big thing
there was not just one but also <a href="https://aws.amazon.com/blogs/aws/introducing-amazon-cloudfront-vpc-origins-enhanced-security-and-streamlined-operations-for-your-applications/">a second announcement</a> of the same feature on that very same day.</p>

<p>You should read the details how to deploy VPC Origin from above blog posts but in short this allows us to
serve content via CloudFront from EC2, ALB or NLB in private subnets. An Origin will be deployed as AWS
managed ENIs in your subnets.</p>

<p>For this to work you must have an internet gateway attached to VPC but you
don’t have to have a route pointing to it. This is just a safety measure preventing building an unallowed
access from internet, similar to <a href="/aws/vpc/internet/globalaccelerator/2019/09/02/no-internetgw.html">Global Accellerator -case</a> in the past. There is also
<a href="https://docs.aws.amazon.com/AmazonCloudFront/latest/DeveloperGuide/private-content-vpc-origins.html">the usual small print</a> you should read before deploying.</p>

<p>Obviously adding CloudFront will enchance user experience by cutting down the latency between browser and service.
But I don’t think this is the most important aspect of “better” in this case. This setup solves the problem
many development teams have with centralized ingress where <a href="https://docs.aws.amazon.com/whitepapers/latest/building-scalable-secure-multi-vpc-network-infrastructure/using-network-firewall-for-centralized-ingress.html">front-end load balancer is placed into central
VPC</a> out of their reach.</p>

<p>I believe this way it is possible to both enable developers to deploy their service independently of network team
using any tools and workflows they are familiar with, and at the same time not have route (as routable public IPs)
from the internet to every VPC. Keeping both devs and net/sec happy is no small feat!</p>

<p><a href="/img/vpc-dealers/result.png"><img src="/img/vpc-dealers/result.png" hspace="40" width="86%" /></a></p>

<h3 id="with-little-effort">With Little Effort</h3>

<p>All of above would be nice but not very impressive if that would only apply to new VPCs build from ground-up,
or require re-deploying all existing resources. Luckily you can apply these changes to existing VPCs with
running services with only a short glitch.</p>

<ul>
  <li>First deploy internal ALB and register the same targets as with original internet facing ALB.</li>
  <li>Configure CloudFront VPC Origin pointing to internal ALB.</li>
  <li>Attach TGW for cental egress into private subnets.</li>
  <li>Change default route of private subnets from NAT GWs to TGW attachment.</li>
  <li>Switch DNS from ALB to CloudFront and wait until there is no more traffic to ALB.</li>
  <li>Delete NAT GWs and attached EIPs. If you suspect you might have out-bound integrations that depend
on your IP address, you can keep EIPs for a moment. Just don’t forget to delete them once you are sure you
don’t need them.</li>
  <li>Delete ALB, public subnets and public route table(s).</li>
  <li>Done.</li>
</ul>

<h2 id="summary">Summary</h2>

<p>In this episode of VPC Dealers we modernised a classic VPC architecture to run better, cheaper and be more resilient
to operator errors. All this without sacrificing developer team independence or having a service break.
I’m sure there will be many happy deployments ahead with new improved VPC architecture.</p>

<p>If you liked this, please stay tuned for next episode of VPC Dealers by subscribing <a href="/feed.xml">RSS-feed</a>.</p>

<p>Until then. Ta-Da!</p>]]></content><author><name>kallu</name></author><category term="aws" /><category term="vpc" /><category term="origin" /><category term="network" /><category term="redesign" /><summary type="html"><![CDATA[In this episode I've inherited an old web service build on common VPC design for its time. Architecture is basicly ok and fit for the purpose. Public and private resources are in their separate subnets. Only the application load balancer (ALB) is exposed to internet and EC2 instances in private subnets are protected from direct internet access. But today we can do better and with little effort, make it run better, cheaper and be more secure. Pick any 3 ;-)]]></summary></entry><entry><title type="html">Access Red Hat Knowledge Base from AWS console</title><link href="https://carriagereturn.nl/redhat/support/knowledgebase/aws/console/2024/11/29/redhatkb.html" rel="alternate" type="text/html" title="Access Red Hat Knowledge Base from AWS console" /><published>2024-11-29T10:00:00+00:00</published><updated>2024-11-29T10:00:00+00:00</updated><id>https://carriagereturn.nl/redhat/support/knowledgebase/aws/console/2024/11/29/redhatkb</id><content type="html" xml:base="https://carriagereturn.nl/redhat/support/knowledgebase/aws/console/2024/11/29/redhatkb.html"><![CDATA[<p>At the age of genAI it is valuable to have access to expert generated content and not just trying out random advices found from internet forums full of chatbots. If you are working as linux admin, and especially when using RHEL or one of it’s <a href="https://en.wikipedia.org/wiki/Red_Hat_Enterprise_Linux_derivatives">derivative distributions</a> Red Hat Knowledge Base can become very helpful resource.</p>

<p>The Red Hat Knowledge Base is an extensive repository of resources related to Red Hat products and services. It contains technical documentation, how-to articles, FAQs, and community contributions designed to help users effectively utilize Red Hat technologies, such as Red Hat Enterprise Linux, OpenShift, Ansible, and more. Users can search the knowledge base to find solutions to issues or to learn more about specific features and functionality of Red Hat products.</p>

<p>Unfortunately good things are seldom free. To access Red Hat Knowledge Base content you would typically need:</p>

<ul>
  <li>
    <p>Red Hat Account: You should have an active Red Hat account. This is required to log in and access specific articles or support resources.</p>
  </li>
  <li>
    <p>Subscription: Some content in the knowledge base may require a valid subscription to Red Hat products. This grants access to more in-depth resources and support.</p>
  </li>
</ul>

<p>Problem can be not just the price of subscription but the purchase process of your company, especially if you don’t use RHEL but one of it’s free derivatives. Luckily AWS console has a shortcut for you …</p>

<h2 id="access-red-hat-knowledge-base-from-fleet-manager">Access Red Hat Knowledge Base from Fleet Manager</h2>

<p>This is actually an old news but you might have missed it if RHEL administration on EC2 wasn’t your main focus back in <a href="https://aws.amazon.com/about-aws/whats-new/2021/11/amazon-ec2-red-hat-knowledgebase/">2021 when the feature was announced</a>. All you need is an EC2 instance running RHEL AMI registered to AWS Systems Manager (SSM). Unfortunately RHEL AMIs don’t come with SSM agent pre-installed but you have to take care of installation yourself or bake your own AMI from one provided by Red Hat.</p>

<p><a href="https://docs.aws.amazon.com/systems-manager/latest/userguide/agent-install-rhel-8-9.html">SSM agent can be installed</a> to RHEL 8 &amp; 9 with the following user-data script. This will take care of adding Python 3 and downloading SSM agent from S3 bucket in the same region as your instance is. Note that if you are deploying this from Cloudformation template you don’t have to resolve <code class="language-plaintext highlighter-rouge">REGION</code> in the script but REGION can be supplied during stack creation.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>#!/bin/bash
ARCH="linux_amd64"
REGION=`curl -s http://169.254.169.254/latest/meta-data/placement/region`
[ `uname -m` == "aarch64" ] &amp;&amp; ARCH="linux_arm64"
sudo dnf install python3
sudo dnf install -y https://s3.${REGION}.amazonaws.com/amazon-ssm-${REGION}/latest/${ARCH}/amazon-ssm-agent.rpm
sudo systemctl enable amazon-ssm-agent
sudo systemctl start amazon-ssm-agent
</code></pre></div></div>

<h2 id="now-go-build">Now Go Build</h2>

<p>To make testing easy, I wrote you a <a href="/files/redhatkb/rhkb.yaml">template for VPC with single t2.small instance</a> with supporting resources as shown below. Note that default AMI ID is for RHEL9 at eu-west-1. If you deploy to any other region you must find the RHEL9 AMI ID yourself *</p>

<p><strong>*</strong> <a href="https://aws.amazon.com/blogs/compute/using-system-manager-parameter-as-an-alias-for-ami-id/">System Manager Paremeter Store</a> has redhat -namespace where you could find aliases for RHEL AMI IDs. Unfortunately this feature is mostly not maintained, except for AWS provided AMIs.</p>

<p><a href="/img/redhatkb/diagram.png"><img src="/img/redhatkb/diagram.png" hspace="20%" width="50%" /></a></p>

<p>After deploying the stack from the template you can navigate to Systems Manager in AWS console, and open Fleet Manager. From Account management -pulldown you will find “Access to Red Hat Knowledgebase” -link.</p>

<p><a href="/img/redhatkb/rhkb2.png"><img src="/img/redhatkb/rhkb2.png" hspace="0%" width="100%" /></a></p>

<p>Clicking the link used to open a new browser window to Red Hat support portal, but now there is a delay build into the process …</p>

<p><a href="/img/redhatkb/wait.png"><img src="/img/redhatkb/wait.png" hspace="15%" width="70%" /></a></p>

<p>After a day or two, you are forwarded to support portal with access “subscription required” content.</p>

<p><a href="/img/redhatkb/rhkb3.png"><img src="/img/redhatkb/rhkb3.png" hspace="15%" width="70%" /></a></p>

<p>You can now access the subscriber content, but to view or write comments you’d have create account and login.</p>

<h2 id="authorization">Authorization</h2>

<p><a href="/img/redhatkb/rhkb-cookie.png"><img src="/img/redhatkb/rhkb-cookie.png" hspace="20" align="right" width="40%" /></a></p>

<p>Access to support portal is granted by <code class="language-plaintext highlighter-rouge">readOnlyAuth</code> cookie from <code class="language-plaintext highlighter-rouge">access.redhat.com</code>. The Cookie
is valid for 24h from authorization at AWS console, so you can continue your session for a moment after your
RHEL instance has been stopped or terminated.</p>

<p>And while it took 2 days from provisioning RHEL EC2 instance for authorization start working, it seems to work other way around too. I was able to refresh my session from AWS console on a day after I shutdown my RHEL instance. But this was just a single test case. You mileage may vary.</p>

<h2 id="summary">Summary</h2>

<p>Fleet Manager link to Red Hat support portal can be useful especially for random needs to find solutions
for common RHEL problems, especially if you prefer expert advices over genAI content. But if this your
full-time job, I’d recommend creating an account to Red Hat portal and maybe keep AWS console as your
backup solution.</p>]]></content><author><name>kallu</name></author><category term="redhat" /><category term="support" /><category term="knowledgebase" /><category term="aws" /><category term="console" /><summary type="html"><![CDATA[At the age of genAI it is valuable to have access to expert generated content and not just trying out random advices found from internet forums full of chatbots. If you are working as linux admin, and especially when using RHEL or one of it's derivative distributions Red Hat Knowledge Base can become very helpful resource. But some of the content requires a subscription ...]]></summary></entry><entry><title type="html">re:Cycle</title><link href="https://carriagereturn.nl/aws/service/lifecycle/eol/2024/11/02/recycle.html" rel="alternate" type="text/html" title="re:Cycle" /><published>2024-11-02T19:00:00+00:00</published><updated>2024-11-02T19:00:00+00:00</updated><id>https://carriagereturn.nl/aws/service/lifecycle/eol/2024/11/02/recycle</id><content type="html" xml:base="https://carriagereturn.nl/aws/service/lifecycle/eol/2024/11/02/recycle.html"><![CDATA[<p><img src="/img/recycle/recycle.png" hspace="20" align="right" width="15%" />
First +10 years of AWS service lifecycle management was just continous stream of
announcements about new services and features. And many (most?) of the services that got
out to public are still there with backwards compatibility all the way to the beginnings.
But it isn’t realistic to think one could just continue building new stuff year after year.
At some point you must start end-of-life process for features and services that no
longer meet customer demand, have been replaced by more efficient alternatives or
have become blocker for future development.</p>

<h2 id="aws-services">AWS Services</h2>

<p>In the past there was no that many complete services being depricated but this year (2024)
AWS has been busy with EOLs. Some of these services weren’t really main stream so if you
haven’t heard of Amazon Lookout for Vision|Metrics|Equipment or Monitron, you’re not alone.
But that was a whole set of industrial AI/ML services that were put into maintenance mode, 
with many others, in October 2024.</p>

<p>Similar, but more main stream, clean up did happen in development tools where
CodeCommit, CodeStar and Cloud9 are no longer available for new customers.</p>

<p>Common way for AWS to depricate a service or feature, is block new customers from start using it.
It can be that your existing deployments will continue work, and you might be able to make changes
too (but not always) or you could even be able to deploy new instances of service on accounts where
you had given service in use.</p>

<p>Any deprication can have a major effect for a customer if critical services are build to
depend on it, but in global scale there is one breaking change that will dwarf all others …</p>

<h3 id="ec2-autoscaling-launch-configurations">EC2 Autoscaling Launch Configurations</h3>

<blockquote>
  <p>Through a series of deprecations spanning multiple years, AWS is slowly killing off EC2 Auto Scaling Launch Configurations in favor of EC2 Launch Templates. On October 1, 2024, only those accounts that have previously used Launch Configurations can continue to do so.</p>
</blockquote>

<p>While this has been public information since October 2021, I think there are still a lot of ‘legacy’
Cloudformation and Terraform code depending on launch configuration being available.
Just a simple search from <a href="https://github.com/aws-samples">aws-samples github repositories</a> found +180 references to 
Cloudformation resource type <code class="language-plaintext highlighter-rouge">AWS::AutoScaling::LaunchConfiguration</code></p>

<p>Now after October 1st, 2024, those templates will continue work if you have previously used launch configurations on the account, but on any account that was created after October 1st, or didn’t previously have launch configurations, the same template will fail.</p>

<p><a href="https://docs.aws.amazon.com/autoscaling/ec2/userguide/migrate-launch-configurations-with-cloudformation.html">Conversion process from launch configuration to launch template</a> isn’t very complex in
most of cases, but tricky part can be finding the all the code and CI/CD processes. For
services that are not in active development mode this can be a challenging reverse engineer task.</p>

<h2 id="3rd-party-software">3rd Party Software</h2>

<p>When the service is all about hosting 3rd party software, there is obvious dependency
to availability and support for given software version. Major services in this category are</p>

<ul>
  <li><a href="https://docs.aws.amazon.com/eks/latest/userguide/kubernetes-versions.html">EKS</a></li>
  <li>RDS for <a href="https://docs.aws.amazon.com/AmazonRDS/latest/PostgreSQLReleaseNotes/postgresql-release-calendar.html">PostgreSQL</a> / <a href="https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/CHAP_SQLServer.html">SQL Server</a> / <a href="https://docs.aws.amazon.com/AmazonRDS/latest/OracleReleaseNotes/Welcome.html">Oracle</a> / <a href="https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/MySQL.Concepts.VersionMgmt.html">MySQL</a> / <a href="https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/MariaDB.Concepts.VersionMgmt.html">MariaDB</a> / <a href="https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/Db2.Concepts.VersionMgmt.html">Db2</a></li>
  <li><a href="https://docs.aws.amazon.com/lambda/latest/dg/lambda-runtimes.html">Lambda runtimes</a></li>
  <li>… plus others like Elasticache, OpenSearch and even Amazon Linux.</li>
</ul>

<p>For databases minor and even major version upgrades are often backwards compatible, so your
application will work with next version without changes. Upgrade effort is then
reduced to testing (which shouldn’t be underestimated) and scheduling the upgrade.
However it can be your application is certified only with certain versions and while it
could work after upgrade, loosing your application vendor support might be too risky for
business critical service.</p>

<p>Kubernetes control plane (EKS) upgrades <a href="https://docs.aws.amazon.com/eks/latest/userguide/update-cluster.html">takes a bit more planning</a> because there is no
warranty new version is compatible with previous one. It is your responsibility to judge if breaking
changes between versions are something you should be worried or not. To resolve upgrade issues
you might need to make changes to your applications or find a new combination of versions for
middleware services you run in the cluster.</p>

<p>If you feel dead-lines for RDS and EKS updates are coming too fast for you, there is <a href="/aws/techdebt/extented/support/2024/01/27/extentedsupport.html">an option
to buy extra time but it doesn’t come for free</a>.</p>

<p>For Lambda the serverless promise was you don’t need to manage servers (OS) or runtimes. While
that is true, no-one ever said you can just deploy and be done with it. When Lambda runtime is deprecated
functions you have deployed will continue working but you can not create any new or update existing
functions, ie. deploying bug fixes or new features to your code isn’t possible. <a href="https://aws.amazon.com/blogs/compute/announcing-end-of-support-for-python-2-7-in-aws-lambda/">Python 2.7 EOL
announcement</a> is old but good example how Lambda runtime EOL process works.</p>

<h2 id="keep-yourself-updated">Keep Yourself Updated</h2>

<p>I wish there would be a single timeline of all EOL plans for AWS services. Unfortunately there isn’t, or if you find one, please let me know too. The Best thing I’ve found is <a href="https://github.com/SummitRoute/aws_breaking_changes/blob/main/README.md">aws_breaking_changes -git repo</a> mainteined by <a href="https://github.com/0xdabbad00">Scott Piper</a>. README has the list recent and upcoming deprecations, or breaking changes. Past changes are archieved in <a href="https://github.com/SummitRoute/aws_breaking_changes/blob/main/archive.md">archive.md</a>.</p>

<p><em>EDIT</em>: Also aws-news.com dedicated feed for <a href="https://aws-news.com/custom_feed/qCOnC">service deprecations</a> is worth subscribing to.</p>

<p>Other good sources are AWS service documentation (e.g. above links for RDS, EKS &amp; Lambda) and subscribing
<a href="https://aws.amazon.com/blogs/">AWS blogs</a> from categories that are most relevant for you.</p>]]></content><author><name>kallu</name></author><category term="aws" /><category term="service" /><category term="lifecycle" /><category term="eol" /><summary type="html"><![CDATA[First +10 years of AWS service lifecycle management was just continous stream of announcements about new services and features. And many (most?) of the services that got out to public are still there with backwards compatibility all the way to the beginnings. But it isn't realistic to think one could just continue building new stuff year after year. At some point you must start end-of-life process for features and services that no longer meet customer demand, have been replaced by more efficient alternatives or have become blocker for future development.]]></summary></entry><entry><title type="html">Anonymous S3 Access</title><link href="https://carriagereturn.nl/aws/iam/s3/anonymous/2024/07/31/anonymous-access.html" rel="alternate" type="text/html" title="Anonymous S3 Access" /><published>2024-07-31T10:00:00+00:00</published><updated>2024-07-31T10:00:00+00:00</updated><id>https://carriagereturn.nl/aws/iam/s3/anonymous/2024/07/31/anonymous-access</id><content type="html" xml:base="https://carriagereturn.nl/aws/iam/s3/anonymous/2024/07/31/anonymous-access.html"><![CDATA[<p>I’ve been hanging around at <a href="https://repost.aws/">repost.aws</a> for a while because the best way to keep your
skills fresh is to see what challenges other people have in real life and check if can solve those.
And maybe learn something new during the process. That is also how this post got started.</p>

<blockquote>
  <p>I am a complete newby to AWS and HTML and want to create a pdf file sharing solution for my social group. I have created a <strong>s3 bucket</strong> with my pdf’s in a folder. when I specify a single file the web page works ok ie</p>
</blockquote>

<blockquote>
  <div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&lt;iframe src="Songs/my file name.pdf""&gt; &lt;/iframe&gt;
</code></pre></div>  </div>
</blockquote>

<blockquote>
  <p>I cannot find a way to specify all the <strong>files using a wild card</strong> and I cannot specify each file individually so how can it be done.</p>
</blockquote>

<p>When you ignore some of the context, what is left is the question how to list objects from S3 bucket on a webpage or an application. This may first sound trivial but keep reading …</p>

<h2 id="server-side-solutions">Server-side solutions</h2>

<p>Obvious solution would be rendering the page on server-side. You could write a piece of code to list
the bucket content and transform that into something that can be presented in browser or application.
As everyone should know by now, inserting AWS API key (or any secrets) into your code base is serious
anti-pattern. Luckily this is very easy to avoid using <a href="https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/iam-roles-for-amazon-ec2.html">instance profiles</a> or <a href="https://docs.aws.amazon.com/lambda/latest/dg/lambda-intro-execution-role.html">IAM roles</a> that take transparently care of assigning temporary API keys for your code to use.</p>

<p>And even if you would be running server outside of AWS, there is similar functionality (with little bit more setup effort) called <a href="https://docs.aws.amazon.com/rolesanywhere/latest/userguide/introduction.html">IAM Roles Everywhere</a> you could use instead of static API keys.</p>

<p>All above makes server-side implementation too trivial to be interesting. But what if you don’t want
to have any of application code running on your servers, including serverless solutions ;-)</p>

<h2 id="problem-with-client-side-secrets">Problem with client-side secrets</h2>

<p>Challenge with client-side solutions isn’t in writing the code that can run in a browser or creating
a client application. Just pick the <a href="https://aws.amazon.com/developer/tools/">SDK for your favourite language</a> and go build! Problem is
how to authenticate for AWS API without exposing your API key &amp; secret to the client. By default you
should assume anything distributed with client will be exposed to the public. You could craft the IAM
policy very carefully so it would allow access to things that are already public but even then there
is a risk that you made a small mistake in IAM policy (we all know how easy that is) or someone
accidentially alters the policy later.</p>

<p><a href="https://aws.amazon.com/cognito/getting-started/">Amazon Cognito</a> helps in building end-user identity and access management. It can also
provide temporary access to AWS APIs similar to instance profiles and IAM roles for server-side solutions. Cognito also allows you to define a separate IAM role with limited permissions for guest users who are not authenticated. This removes unnecessary login step, but still enables you to use temporary, limited privilege credentials to access AWS resources.</p>

<p>While Cognito helps when you want to provide access to AWS resources for authenticated users, 
identity pool and permission <a href="https://docs.aws.amazon.com/sdk-for-javascript/v2/developer-guide/s3-example-photos-view.html">setup is bit complex</a> if you only want to provide
anonymous access to S3 (or similar).</p>

<h2 id="anonymous-access">Anonymous access</h2>

<p>For S3 there is also truly anonymous access, meaning you don’t need any API key to access public
buckets and objects. Easiest way to test this is with <a href="https://awscli.amazonaws.com/v2/documentation/api/latest/reference/s3/ls.html">AWS S3 CLI</a>. When you add
<code class="language-plaintext highlighter-rouge">-no-sign-request</code> option, no credentials are used but I can still get the list of objects.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>% aws s3 ls s3://s3.carriagereturn.nl/ --region eu-north-1 --no-sign-request
2024-07-31 18:42:27     119409 hello.jpg
2024-07-31 18:41:17         15 hello.json
2024-07-31 18:41:17         12 hello.txt
</code></pre></div></div>

<p>And to verify I didn’t have any credentialsi, the same command fails when I try to sign the request.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>% aws s3 ls s3://s3.carriagereturn.nl/ --region eu-north-1                  
An error occurred (InvalidAccessKeyId) when calling the ListObjectsV2 operation: The AWS Access Key Id you provided does not exist in our records.
</code></pre></div></div>

<p>For above to work, <a href="https://docs.aws.amazon.com/AmazonS3/latest/userguide/bucket-policies.html">bucket policy</a> must allow <code class="language-plaintext highlighter-rouge">s3:ListBucket</code> and <code class="language-plaintext highlighter-rouge">s3:GetObject</code>.</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
    </span><span class="nl">"Version"</span><span class="p">:</span><span class="w"> </span><span class="s2">"2012-10-17"</span><span class="p">,</span><span class="w">
    </span><span class="nl">"Statement"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
        </span><span class="p">{</span><span class="w">
            </span><span class="nl">"Sid"</span><span class="p">:</span><span class="w"> </span><span class="s2">"PublicRead"</span><span class="p">,</span><span class="w">
            </span><span class="nl">"Effect"</span><span class="p">:</span><span class="w"> </span><span class="s2">"Allow"</span><span class="p">,</span><span class="w">
            </span><span class="nl">"Principal"</span><span class="p">:</span><span class="w"> </span><span class="s2">"*"</span><span class="p">,</span><span class="w">
            </span><span class="nl">"Action"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
                </span><span class="s2">"s3:GetObject"</span><span class="p">,</span><span class="w">
                </span><span class="s2">"s3:ListBucket"</span><span class="w">
            </span><span class="p">],</span><span class="w">
            </span><span class="nl">"Resource"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
                </span><span class="s2">"arn:aws:s3:::s3.carriagereturn.nl"</span><span class="p">,</span><span class="w">
                </span><span class="s2">"arn:aws:s3:::s3.carriagereturn.nl/*"</span><span class="w">
            </span><span class="p">]</span><span class="w">
        </span><span class="p">}</span><span class="w">
    </span><span class="p">]</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>As the challenge was to create a webpage with dynamic listing of bucket content
I created a small demo project using AWS Javascript SDK V3 and anonymous access
to S3 API.</p>

<p><img src="/img/anonymous-access/webdemo.png" width="50%" hspace="10" align="right" /></p>

<p>You can get the code from <a href="https://github.com/kallu/aws-js-sdk-anonymous-access/tree/main">GitHub repository</a> and build it yourself.
If things worked as planned you should see page similar to this screenshot.</p>

<p>In earlier versions of Javascript SDK there was <code class="language-plaintext highlighter-rouge">s3.makeUnauthenticatedRequest</code> method
but in current versions that doesn’t exists and documentation isn’t very helpful either :-(</p>

<p><a href="https://github.com/aws/aws-sdk-js-v3/issues/2321">Work-a-round</a> is to define <code class="language-plaintext highlighter-rouge">signer</code> as shown below.</p>

<div class="language-javascript highlighter-rouge"><div class="highlight"><pre class="highlight"><code>    <span class="c1">// Initialize an S3 service with anonymous credentials.</span>
    <span class="kd">const</span> <span class="nx">s3</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">S3</span><span class="p">({</span>
        <span class="na">region</span><span class="p">:</span> <span class="nx">region</span><span class="p">,</span>
        <span class="na">signer</span><span class="p">:</span> <span class="p">{</span>
            <span class="na">sign</span><span class="p">:</span> <span class="k">async </span><span class="p">(</span><span class="nx">request</span><span class="p">)</span> <span class="o">=&gt;</span> <span class="nx">request</span>
        <span class="p">}</span>
        <span class="p">...</span>
</code></pre></div></div>

<h2 id="summary">Summary</h2>

<p>If you think you must include static credentials with any client, or server, side code, think again.
As shown above, there are multiple ways to avoid using long term AWS API secrets. In some cases you
can also make the code work without any API authentication. Yes, it is only limited S3 use-cases
but when that is all you need, anonymous access can simplify your application architecture and
avoid running application code on server-side, making the application truly serverless ;-)</p>

<p>PS. If you are looking for a bit more ambitious implementation of S3 access from a browser, using Cognito
authentication, take a look at <a href="https://github.com/aws-samples/public-file-browser-for-amazon-s3/">public-file-browser-for-amazon-s3</a>.</p>]]></content><author><name>kallu</name></author><category term="aws" /><category term="iam" /><category term="s3" /><category term="anonymous" /><summary type="html"><![CDATA[I've been hanging around at repost.aws for a while because the best way to keep your skills fresh is to see what challenges other people have in real life and check if can solve those. And maybe learn something new during the process. That is also how this post got started ...]]></summary></entry></feed>